RSS ⧉

Kyle's blyg

Kyle Mathews

thread

The Dutch agricultural economy of the 1500s–1700s was remarkably sophisticated. Rather than growing enormous quantities of staple grains, farmers in the commercialized coastal provinces specialized in dairy, livestock, vegetables, and industrial crops that could command higher prices relative to the land they occupied.

The really interesting part is that this wasn't primarily a story of luxury goods. It was about specialization, processing, and access to enormous markets—including markets hundreds of miles away.

What did Dutch farmers specialize in?

Product Main regions Where the value came from
Cheese North Holland, particularly Edam, Alkmaar and Gouda's surrounding region Converting perishable milk into a durable, exportable product
Butter Friesland, South Holland Supplying affluent urban consumers and foreign markets
Fattened cattle Holland Importing relatively inexpensive livestock, fattening it on rich pastures, then selling it for meat
Vegetables Market gardens around Dutch cities Intensive cultivation of fresh produce for nearby urban customers
Madder Zeeland, South Holland Producing valuable red dye for Europe's textile industry
Flax and hemp Zeeland, South Holland, Utrecht Supplying linen, rope, sails and other manufactured goods
Hops and oilseeds Various specialized districts Feeding breweries and supplying oil for lighting, soap, paint and food
Flower bulbs Holland Serving a smaller, affluent ornamental-plant market

These were regional specialties rather than crops grown uniformly across the Republic. Inland agricultural districts remained considerably more traditional. OECD +3

1. Dairy was the biggest success

Gezicht op het Waaggebouw te Alkmaar | IZI Travel

Aelbert Cuyp | The Large Dort | NG961 | National Gallery, London

File:Aelbert Cuyp - Cows with a Milkmaid in a Farmyard.jpg - Wikimedia Commons

Waag en Kaasmarkt te Alkmaar | Free Photo Illustration - rawpixel

Farmyard Scene Our beautiful Wall Art and Photo Gifts include Framed Prints, Photo Prints, Poster Prints, Canvas Prints, Jigsaw Puzzles, Metal Prints and so much more

A river landscape with cattle watering and a milkmaid by Aelbert Cuyp on artnet

The Dutch developed a sophisticated dairy economy long before the Golden Age.

By around 1500, historian Oscar Gelderblom estimates that half to two-thirds of Holland's households participated in commercial dairying. In the 1640s, Gouda's cheese market alone handled an average of approximately 4.9 million pounds of cheese annually. Erenow +1

The economics were attractive for several reasons.

First, making hard cheese transformed milk from something that spoiled quickly into a product that could be stored and transported across Europe. This massively expanded the accessible market.

Second, dairy converted land suited to grass into products that could generate substantially more commercial revenue than struggling to grow grain on that same land.

Third, Dutch farmers had improved livestock management, particularly winter stall-feeding and careful cattle husbandry. The agricultural system supported reliable production instead of depending entirely on seasonal grazing.

And finally, dairying created multiple revenue streams: milk, cheese, butter, calves, meat, and manure.

Cheese was particularly successful because it was both a processed food and a convenient trade commodity. A merchant could purchase thousands of standardized wheels, assemble a cargo, and sell them in France, England, Germany, or further afield. dokumen.pub +2

2. Industrial crops were surprisingly lucrative

These were not crops people ate. They were agricultural inputs for some of Europe's fastest-growing manufacturing industries.

Take madder, a plant cultivated for the red dye extracted from its roots.

meekrap

Zeeland farmers grew madder, harvested its roots, and had them dried, cleaned and ground into dye powder at specialized processing facilities called meestoven.

Merchants often financed the processing and exported the finished dye to textile manufacturers abroad. Historical evidence from 1690 suggests more than 90% of Zeeland's processed madder was exported. dokumen.pub +1

The economic difference from wheat is substantial. Instead of selling a commodity primarily valued as calories, the farmer supplied an industrial raw material valuable for its chemical properties. The crop could support intensive cultivation and specialized processing because textile manufacturers were willing to pay for the dye.

The same pattern applied to hemp for rope and sails, flax for linen, hops for beer and oilseeds for industrial oils.

This is a primitive version of producing specialty chemicals or industrial feedstocks instead of bulk commodities.

3. Market gardening exploited urban demand

Dutch cities were unusually large and wealthy relative to the surrounding countryside.

Urban customers wanted vegetables, fresh milk, meat and other foods that were inconvenient or expensive to transport long distances.

Farmers near these cities could profit by growing labor-intensive crops on relatively small plots, sometimes with multiple harvests or rotations.

The highly developed canal and barge network enlarged the practical radius of these markets, allowing horticultural regions to serve cities beyond their immediate neighborhoods. EH.net +1

This is an important distinction: high-value horticulture could generate more revenue per acre while employing more people per acre. That is different from increasing agricultural output per worker.

4. The real breakthrough was capturing the entire market opportunity

The Dutch developed an unusually effective system that connected specialization to customers.

How Dutch agricultural specialization worked

Baltic grain imports

Cheap staple calories from Polish and Baltic farmland

Dutch farmland freed to specialize

Dairy, meat, market gardens, dyestuffs and industrial crops

Processing and commercial infrastructure

Cheesemaking, dye mills, weigh houses, canals, merchant networks

Domestic and international markets

Amsterdam, other Dutch cities and export customers throughout Europe

Conceptual model of the Dutch agricultural economy, particularly Holland and the coastal provinces.

Three features made this arrangement work unusually well.

Cheap transport. Ships made it economical to import bulk grain while exporting more valuable agricultural goods. The Baltic grain trade was sufficiently important that Dutch merchants called it their mother trade.

Sophisticated markets. Village and urban weigh houses established trustworthy quantities for transactions. Merchants could aggregate small producers' output and find buyers at a scale individual farmers couldn't. Historian Jessica Dijkman's research emphasizes how these institutions lowered search, information and transaction costs. Utrecht University Repository

Capital investment. Wealthy urban investors financed drainage, land reclamation, farms, and processing infrastructure. Dutch agricultural specialization became an integrated commercial enterprise rather than a collection of subsistence farms.

There was also an important environmental push: centuries of drainage had caused peat soils in Holland to subside, making much of the land less suitable for grain but still usable as pasture. Farmers were partly forced to specialize, and trade made that specialization viable. Utrecht University

But who actually captured the additional value?

Not just farmers.

Landowners captured some through higher rents. Merchants captured returns from financing, trading and distributing agricultural products. Processors and transport operators earned income too.

By around 1560, approximately 30–35% of Holland's land was owned by urban residents and institutions. Their ownership share expanded substantially in subsequent decades. Many farmers increasingly operated as commercial tenants rather than independent landowners. Academia

The benefits were real, but unevenly distributed.

It's also worth distinguishing price increases from productivity improvements. While nominal rents rose dramatically in the sixteenth and seventeenth centuries, a recent historical reconstruction estimates real land rents in Holland rose by about 50% between 1500 and 1650—not tenfold in purchasing-power terms. Academia

The fascinating comparison with England

The two agricultural revolutions emphasized different forms of productivity:

  • The Dutch developed sophisticated, specialized agriculture embedded in regional and international trade networks. Some activities maximized value per acre; others, particularly commercial dairy farming, economized on labor.

  • England eventually developed exceptionally high agricultural labor productivity through larger farms, better organization, livestock management and improved rotations.

The Dutch model looks surprisingly modern: import low-cost commodities, specialize in valuable production, and use infrastructure and market access to multiply economic opportunities.

But one implication is worth emphasizing: the agricultural revolution wasn't just about what happened on farms. It was about removing the requirement that every region, and every farmer, produce their own food.

Once farmers could reliably buy their bread rather than grow their grain, they could organize their land and labor around whatever they were comparatively best at producing. That was an enormous expansion of the possible economic arrangements—and much of it happened centuries before industrialization.
read the thread →

Created: Nov 10, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

Hosted updater service (Cloudflare OAuth)

A centrally hosted service manages upgrades for independently owned Cloudflare installations. Users click Update inside their applications, authorize the service through Cloudflare OAuth, and the service downloads the appropriate GitHub release, applies D1 migrations, and deploys the new Worker. No GitHub account, CLI, or local tooling is required. Authorization can be temporary rather than persistent. This offers the simplest user experience while preserving independent ownership, but requires you to build and maintain a deployment orchestration service.

from Venkatesh Rao's Blyg ↗ · excerpt of v1

Yeah I researched this a while ago for Blygger — Cloudflare has shipped all the controls needed for someone to give a centralized upgrading tool enough power to upgrade their studio whenever.

read the thread →

Created: Nov 8, 2026

One odd thing I didn't know but learned this year's election is that senators in deep red states basically don't campaign, refuse to debate their opponent etc.

Senator Cindy Hyde-Smith from Mississippi (who looks like they'll be loosing to their Democrat challenger Scott Colom) is one such. If Colom wins he'll be the first Democrat elected since 1982 and the first black senator since just after the civil war!

Colom made fun of her for this in a a few brilliant ads https://talkingpointsmemo.com/wp-content/uploads/2026/11/9fn80ox3agHvOOWT.mp4 & https://www.youtube.com/watch?v=Nga2Q207-58

Created: Nov 7, 2026

In response to AMMDI Blyg ↗

thread · 1 quoted

Alan Kay's answer to Can an “AI command line” replace the GUI as the primary user experience for computers, assuming the technology improves and irrespective of today’s state? - Quora

from AMMDI Blyg ↗ · excerpt of v1

https://www.quora.com/Can-an-AI-command-line-replace-the-GUI-as-the-primary-user-experience-for-computers-assuming-the-technology-improves-and-irrespective-of-today-s-state/answer/Alan-Kay-11

A good UI is much more than a command environment, it also needs to teach in various ways, it needs to be safely explorable in many ways, etc.

Yes — this is exactly what I say when talking to people about AI replacing SaaS — SaaS isn't just a tool — it's a deeply thought through and optimized teaching tool for how to do a business process. A SaaS vendor knows an immense amount about a specific way of working by virtue of helping 1000s of companies do that task — that knowledge is embedded in the app.

read the thread →

Created: Nov 7, 2026

thread

My wife and I got curious what Europeans used for sour flavors before lemons.


Before lemons, Europeans had a much wider range of sour ingredients than we use today. Lemons didn't introduce acidity so much as gradually replace a collection of local sources, some of which arguably suited particular dishes better.

The main pre-lemon sources

  • Verjuice: juice of unripe grapes or crabapples. Bright and tart without vinegar's fermented edge, it was used everywhere in medieval sauces, meat dishes, and sometimes desserts. It's the closest equivalent to lemon juice.
  • Gooseberries and currants: especially important in Northern Europe for pies, sauces, puddings, and preserves. Green gooseberries are very sour and high in pectin.
  • Crabapples and sour apples: used for tart sauces, desserts, and jellies, and to add acid and pectin to other preserves. One account from 1305 describes gathering crabapples specifically to make sauce.
  • Sorrel and other sour greens: a lemony tang from oxalic acid, used in savory dishes such as soups, sauces, and fish.
  • Vinegar, sour wine, sour ale, and fermented dairy: the most reliable year-round options, and essential for pickling and sweet-sour sauces.

Medieval cooks loved sweet-sour flavors, often pairing vinegar or verjuice with honey, sugar, or dried fruit. Citrus was a luxury, especially in the north. In English cookbooks, citrus juice shows up around 1584 and becomes more common after that.

Baking and preserves

Sour fruits supplied tartness in pies, and sour milk or buttermilk (later cream of tartar) helped with leavening. Nothing really replaced lemon zest, though. Spices, floral waters, and herbs filled that role with different flavors.

Jam is the most telling case. Modern recipes add lemon juice because pectin needs acid to set. Historical cooks instead mixed low-pectin fruit with high-pectin fruit like apples or gooseberries, or simply cooked preserves down further. Crabapples, currants, gooseberries, cranberries, sour apples, and quinces can make jelly with sugar alone, and Mrs. Beeton's 1861 gooseberry jelly is just gooseberries and sugar. One caveat: for modern shelf-stable canning, don't swap these in for bottled lemon juice without a tested recipe.

Beyond Europe

Other cuisines had their own long-standing souring traditions rather than lemon substitutes. Examples include tamarind, amchur (dried green mango), kokum, sumac, pomegranate, and yogurt.

The takeaway

Lemons probably narrowed everyday sour flavors in Northern European and American cooking. A medieval cook might use verjuice with meat, sorrel with fish, crabapple sauce with game, and gooseberries in a pudding. Today we'd squeeze a lemon over all four. That's convenient, but we've lost some distinctive flavors. Verjuice, redcurrants, crabapples, and gooseberries seem especially worth reviving for home preserving.

read the thread →

Created: Nov 5, 2026

In response to Pioneering Spirit (Blyg) ↗

thread · 1 quoted

Did IT folks talk about search in 1992? My sense is no. I wonder what new concepts will be commonplace in the AI era to typical IT folks though not in the water widely today.

from Pioneering Spirit (Blyg) ↗ · snapshot of v1

It was more specialized for sure but there were tons of search systems still then. Lots of books published before then on search.

read the thread →

Created: Nov 5, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

I'm more-or-less a single issue voter — severely weaken Trump's movement. The odd thing is that doesn't make me necessarily want the democrats to win big as it's long been my hypothesis that the only way low-information Trump votes would abandon him is if Trump just completely screws up — which he's been doing a wonderful job at in the 2nd term by surrounding himself loyalists.

from blyg.bricolage.io ↗ · excerpt of v1

Heh I independently said the same thing in my update to my post just now. Only difference is I think the democrats do need to win big. Decisively enough that there’s no doubt Trumpism is not just dead but an embarrassment people want to put behind them and move on from.

from Venkatesh Rao's Blyg ↗ · snapshot of v1

No yeah we're in agreement. I just meant there's got to be a supermajority of Americans permanently pissed at Trump and all his enablers. If we're already there they let's do it but otherwise I'd rather gop stay lightly in power and trump have two more years to fully piss everyone off.

read the thread →

Created: Nov 3, 2026

thread

Election day 😅

I'm more-or-less a single issue voter — severely weaken Trump's movement. The odd thing is that doesn't make me necessarily want the democrats to win big as it's long been my hypothesis that the only way low-information Trump votes would abandon him is if Trump just completely screws up — which he's been doing a wonderful job at in the 2nd term by surrounding himself loyalists.

Josh Marshall gets nicely at this in How Ditching Norms and Guardrails Was Trump’s Undoing

That new level of unpopularity is overwhelmingly due to four things: tariff policy and the impact on inflation; the Iran War and its affect on gas prices and inflation generally; the mass deportation program which has become increasingly unpopular and offends most Americans’ basic sense of decency and American liberties; and the pervasive free-for-all corruption Trump has partaken in and presided over. Judged by affect on public opinion rather than objective importance, the first two seem most important. There are many other depredations that are at least as bad but have been less decisive in shaping public opinion.

Put simply, none of those four things could have happened during his first term because he was surrounded by people who knocked these ideas down, diverted him on to other hobbyhorses or in key cases simply refused to implement them. They all happened since January 2025 because he broke through those guardrails largely by taming the Republican Party and staff his administration strictly with yes people and true believers.

Needless to say, it’s not that Term One went great. And by the end of Term One Trump was finding his way toward assembling the group of toadies and true believers who would characterize Term Two. That’s what made Jan 6th and the larger plot to reverse the 2020 election possible. Still the difference between the two terms is stark. On one level we know this basic difference. Term Two is Trump unleashed. But there’s less attention to how removing them allowed him to become the most unpopular midterm president in at least eighty years. He unleashed himself to do these things by staffing Term Two with people who would faithfully and aggressively implement his most lawless, stupid and fundamentally unpopular policies.

But he is doing real damage so it's probably best he gets actually checked. He'll still do lots of "executive self-soothing" activities (another great Josh Marshall coining) like start stupid wars and build stupid monuments, etc. that'll help drive home the point to low-information voters how badly they've been conned.

Brad Delong's summary of John Ganz's post is also useful. The attempted fascist turn has largely failed to date.

John Ganz distingishes between three things: (1) a fascist movement (which in the Holy Name of the One Who Is Trump certainly leads and stokes); (2) a fascist governmental executive (which Trump wants to lead, and which the corrupt partisan Republican Supreme Court supermajority is eager for him to create via the “unitary executive”); and (3) a fascist state and society (in which “coördination” has been accomplished and we see total bureaucratic and media and substantial cultural submission):

John’s thesis, as I understand it: Right-wing paramilitary street violence has failed to become a sustained political force.

It is largely that failure that has saved us. It is that that has kept us from the roiling boil of martial law and police repression. That roiling boil would have resulted in a régime that turns its punitive power into an effective military and police repressive force. Then that, with sufficient mass mobilization, would have produced the radicalization needed for full-blown fascism proper:

read the thread →

Created: Nov 3, 2026

In response to Pioneering Spirit (Blyg) ↗

thread · 1 quoted

A loose thought: when will human experts stop being the gold standard for ground truthing niche classification problems? That's already shifted in somewhat in domains like radiology but even there there's issues with classifying in the wild of lots of hospital with messy sensors. Is this something that will generalize in the coming years with AI?

from Pioneering Spirit (Blyg) ↗ · snapshot of v1

This has happened quite a few times. LLM's capabilities are quite jagged so they'll be superhuman in some areas and not in plenty others. Jury is still out where though.

  • 1610s — Astronomy: Telescopes replace naked-eye observation for distinguishing celestial objects.

  • 1670s — Microbiology: Microscopes reveal and enable classification of previously invisible organisms.

  • 1860s — Chemistry: Spectroscopy identifies elements by their characteristic light signatures.

  • 1880s — Infectious disease: Microscopy and bacterial cultures replace symptom-based identification of pathogens.

  • 1900s — Blood typing: Laboratory tests establish blood compatibility rather than clinical inference.

  • 1910s — Mineralogy: X-ray diffraction identifies crystal structures more reliably than visual inspection.

  • 1950s — Hematology: Automated cell counters replace manual microscopic blood-cell counting.

  • 1970s — Pregnancy testing: Hormone-based tests replace clinical assessment of pregnancy symptoms.

  • 1980s — Forensics: DNA profiling supplants expert interpretation of physical resemblance and less discriminating biological evidence for identification.

  • 2010s — Clinical microbiology: Mass spectrometry (MALDI-TOF) automates bacterial species identification, replacing much expert biochemical classification.

read the thread →

v2

Created: Nov 2, 2026 Most recent: Nov 2, 2026, v2

In response to Venkatesh Rao's Blyg ↗

thread · 2 quoted

Chutney literally translates to lickable, so relish would be the closest western concept. Mango chutney is close to a jam. Sweet and sour.

from Venkatesh Rao's Blyg ↗ · excerpt of v1

Heh I didn't realize sweet/sour stuff in english/American traditions is in part inspired by Indian chutneys — tomato ketchup is in part directly descended

  1. 1600s — Southeast Asia: British traders encounter fermented fish sauces, probably including Chinese kê-tsiap.
  2. 1700s — Britain: The British adapt the idea into mushroom, walnut, anchovy, and oyster ketchups. These are salty, savory, concentrated flavorings, often closer to Worcestershire sauce.
  3. Early 1800s — America: Tomato ketchup appears, initially without the substantial sweetness of modern ketchup.
  4. Mid-to-late 1800s — America: Tomato ketchup increasingly incorporates sugar, vinegar, and spices, converging with the existing sweet-and-sour pickle and relish tradition.
  5. 1876 onward — Heinz: Commercial production helps standardize the thick, sweet, acidic tomato sauce we know today.

So there's a remarkable convergence:

Indian fruit chutney American tomato ketchup
Main ingredient Mango, tamarind, tomato, etc. Tomato
Sweetness Sugar or jaggery Sugar
Sourness Tamarind, lime, vinegar Vinegar
Spices Variable, often complex Cloves, allspice, cinnamon, onion
Preservation Cooking, sugar, acid Cooking, sugar, acid
Texture Chunky or smooth Smooth

Modern ketchup is arguably a standardized, industrially optimized tomato chutney, even though the historical lineages are distinct.

What's especially interesting is how much diversity disappeared when Heinz-style ketchup became dominant. Nineteenth-century American cookbooks featured walnut, mushroom, cucumber, and numerous fruit ketchups. Some fruit varieties were essentially smooth, sweet-and-sour relishes.

It makes you wonder what American condiment culture would look like if plum ketchup, peach ketchup, and spiced cherry ketchup had survived alongside tomato ketchup as everyday staples.


current thing is learning herbs as we planted like 17 different European herbs so it's fun to have chatgpt make up or modify recipes to use them. Tarragon and fried sage are two early favorites.

I think the only European herb I’ve used is rosemary, on roast potatoes. No instincts on how they work generally.

from Venkatesh Rao's Blyg ↗ · excerpt of v1

Thyme was the main one I had intuition previously as it's in tons of soups, etc. but lots of recipe generation + experiments are bringing the others along.

read the thread →

Created: Nov 1, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

Is it just me or does blygger feel like it successfully occupies the meso-scale space between blogs and microblogs? Not just in word count but in formality of structure?

Ie it’s not just about length anymore, though blygs do seem to land for me in the 1500-2000 character/200-300 word range. It’s about notebook-type structure and intent on the one hand, and the effect of public versioning which simultaneously encourages seriousness and informality. The perpetual beta vibe.

The optionality of headlines is an important feature I think.

from Venkatesh Rao's Blyg ↗ · snapshot of v1

Yeah I think it's working pretty well for that. Which I'm liking a lot as it's nice to have an informal mesoblogging space. Also cause twitter is useless for discussions. It'll be very interesting to see how this scales.

Research says community spaces is part protocol/interface doesn't and part founder effects (which are quite powerful and persistent). Same software, wildly different cultures: a big Reddit study (35k founders, ~8.6k subreddits) found founders' personalities, inferred from their writing, predicted how long a community lasted and how active it got. Correlational, but the platform was basically held constant. Mastodon's the same: near-identical code, with admins ranging from "rules emerge from the community" to "my server, my values."

The persistence is the surprising part. Newcomers pick up local norms before their first comment. The same person writes civilly in one political subreddit and aggressively in another. Subreddits flooded with newcomers after becoming defaults mostly kept their character. Later arrivals read the room and conform, and the ones who don't fit drift off.

The interface still matters as incentives: showing rules to newcomers bumps compliance, and early upvotes snowball. But cloning a network's UI is easy and cloning its vibe isn't. For a new space, the big early choices are who you invite first, what you visibly celebrate, and who enforces the norms.

read the thread →

v2

Created: Nov 1, 2026 Most recent: Nov 1, 2026, v2

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

Traditional jam is an exercise in preservation. Equal weights of fruit and sugar are common, and boiling removes water and builds a firm set. Compote lives at the other extreme: perhaps 5–25 percent added sugar, gently cooked, often barely thickened. Neither formula quite fits an ice cream ripple. It needs enough sugar and concentration to remain soft in the freezer, but I don't want the strawberry flavor buried under sweetness or transformed into generic cooked fruit.

from blyg.bricolage.io ↗ · excerpt of v1

Took me a while to appreciate the preserves to compote end of the spectrum, since I grew up only knowing the smuckers style fully homogenized and genericized mixed-fruit jam that’s really for children I think. The only exception was marmalade. Smooth jam is to the more adult end of the spectrum what milk chocolate is to dark chocolate. I started eating single-fruit preserves and less processed jams including the fancy Ferber jam primarily to lower sugar load but now I prefer them.

An interesting thing is that as you go towards the compote end and adding spicy flavorings like habaneros or nom-traditional fruit like figs with more fiber-y texture, it starts to taste more and more like chutneys, and work where a chutney would work better, like an accompaniment to savory snacks instead of desserts.

I’m also interested in how pickling fits in. When does salt work better than sugar?

from Venkatesh Rao's Blyg ↗ · snapshot of v1

Part of my motivation is definitely flavormaxxing which is fun to learn about but also has pretty spectacular results. The strawberry jam turned out incredible.

We planted a fairly substantial orchard and we're going into our third year next year so should get a substantial harvest. Compote is a great way to do a short term preservation of fruit as it lasts a few more weeks in the fridge than fresh would and you can down a lot of either straight or on yogurt, cottage cheese, ice cream etc.

I didn't grow up with chutney really as the us mostly lost whatever little savory fruit culinary traditions it has. I do like them at Indian restaurants. I need to study Indian cooking sometime. My current thing is learning herbs as we planted like 17 different European herbs so it's fun to have chatgpt make up or modify recipes to use them. Tarragon and fried sage are two early favorites.

read the thread →

Created: Nov 1, 2026

thread

The Problem with Jam

I started with a practical question: how much sugar should go into strawberry jam? We had frozen homegrown June-bearing strawberries—exceptionally sweet and fragrant—and I wanted to swirl them through French vanilla ice cream. But the question quickly became more interesting: how do you concentrate fruit without cooking away what makes it wonderful?

Traditional jam is an exercise in preservation. Equal weights of fruit and sugar are common, and boiling removes water and builds a firm set. Compote lives at the other extreme: perhaps 5–25 percent added sugar, gently cooked, often barely thickened. Neither formula quite fits an ice cream ripple. It needs enough sugar and concentration to remain soft in the freezer, but I don't want the strawberry flavor buried under sweetness or transformed into generic cooked fruit.

Then I came across Christine Ferber, the Alsatian jam-maker known as the Jam Fairy. Her technique cleverly separates two jobs that conventional jam-making does simultaneously. She macerates fruit with sugar, strains off the released juice, boils that juice into a syrup, and returns the fruit only near the end. The syrup takes the heat; the fruit retains more of its delicate aroma and structure.

This seemed especially promising for our strawberries. Freezing has already ruptured their cells, so they'll give up liquid readily. And with a powerful induction stove and a wide twelve-inch pan, I can reduce that liquid quickly. The goal isn't gentle cooking at all costs. It's to apply heat where it's useful and spare the fruit where it isn't.

But there is a catch. The extracted juice carries much of the aroma too. Evaporating water—even quickly—also strips volatile molecules responsible for fresh, floral notes. It prompted a more radical question: why boil at atmospheric pressure?

Vacuum evaporation lowers water's boiling point dramatically. Commercial jam and fruit-concentrate producers use it to limit heat damage and preserve color. Yet vacuum doesn't solve aroma loss; volatile compounds still escape. Industrial processors sometimes capture those vapors and add the aromatic fraction back. Concentrating flavor turns out to be a problem of separation, not merely temperature.

That led me to freeze concentration. Freeze juice, let it thaw selectively, and collect the early, sugar- and flavor-rich liquid while leaving much of the water behind as ice. It's slow and imperfect—some flavor remains trapped in the ice—but it avoids heat entirely. With frozen orchard fruit already on hand, it's surprisingly approachable.

Next year we expect stone fruit and mulberries, which makes this more than a strawberry experiment. Apricots, in particular, can be extraordinary or disappointingly bland, and I want techniques that reveal the difference rather than flatten it. I'll start by comparing rapid reduction, Ferber-style syrup separation, and freeze concentration, tasting each at matched sweetness and thickness.

The larger lesson is that the best jam may require less cooking, but more deliberate engineering. Sweetness, acidity, texture, freshness, and shelf life are separate variables. Once you stop treating “jam” as a fixed recipe, you can optimize for the thing that actually matters: the flavor of the fruit.

read the thread →

Created: Nov 1, 2026

Out trick or treating and the swarm of kids running from house to house is getting larger and larger.

Created: Oct 31, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

One thought I heard in my early 20s that really hit me was that it's not actually harder to do ambitious really interesting things than much more mundane work. So since you're going to be working anyways, you might as well just set your sights really high.

The most interesting rationale I’ve heard for attempting ambitious things is, “Well, what else are you going to do with your life? Sit around?” This was an ambitious Singaporean guy I met recently. Interesting guy.

from Venkatesh Rao's Blyg ↗ · excerpt of v1

read the thread →

Created: Oct 31, 2026

In response to And Yet Here We Are 🚀 ↗

thread · 1 quoted

Reminds me of https://kevinkelly.substack.com/p/swarm-intelligence

Partially articulated idea:

AI is like microbes in the ecology of thought. Human attention might be at the top of the food chain but the underlying intelligence interactions are complex just like in the food web.

AI seems impressive but that’s because you can see the activity. Bacteria are crazy impressive but we ignore them because we can’t see them.

from And Yet Here We Are 🚀 ↗ · snapshot of v1

read the thread →

Created: Oct 30, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

Would appreciate some testing of these 2 features if you use studio

Browse the thicket from the reader. Every quoted layer in an entry, at any depth, now says whose it is and opens in the reader

from Blygger ↗ · excerpt of v1

A stub's passage is selected in the editor's own preview. The separate chooser pane

from Blygger ↗ · excerpt of v1

from Venkatesh Rao's Blyg ↗ · snapshot of v1

neat! I've been hoping for something like this. I had text highlighted when I hit stub and it didn't quote it like I expected though.

read the thread →

Created: Oct 29, 2026

thread

Programming After Handwritten Code

In his Rails World keynote and follow-up essay, DHH argued that agents would soon write the vast majority of our code.

I don’t write any production code now. Yet programming feels more intellectually demanding than ever.

If I’m no longer writing the code, what exactly am I doing?

My days are full of investigations, experiments, and decisions about what a system should do. What agents still need from me becomes clearest when they get stuck. Why can an agent do something astonishingly difficult, then struggle with a change that seems straightforward?

I think part of the answer is that an implementation cannot reliably tell an agent what we mean the system to do, or how we need it to operate.

Capturing what we mean

When I design a system, I’m developing an understanding of the problem: which concepts matter, how they relate, and why the design should produce the behavior I want. That understanding lets me reason about new cases and decide how the system should change. The code embodies some of that understanding. A fresh agent may still need the reasoning behind the design to extend it.

That understanding also extends to operating the system. Measurements tell us how it behaves today. We still have to decide how much downtime is acceptable, what a recovery must preserve, and what it should cost to operate.

Design and operation inform each other. Data guarantees shape recovery requirements; operating constraints shape which designs are practical.

Some of this knowledge is buried in discussions or known only to maintainers and operators. Some decisions haven’t been made at all. Better access helps with the first problem. The second requires investigation and a decision.

I call a maintained account of this understanding structured intent. It records how we think the system should work, why, under which assumptions, and how we assess it.

Design that can speak back

My work on TanStack DB, a reactive data framework, has become an experiment in preserving that understanding across agent sessions. An investigation can take hours as we explore alternatives, resolve ambiguities, and decide what users should observe. I want the next agent to inherit both the decision and the reasoning behind it.

When we can express a design decision as a rule, we can give future agents a way to check whether their changes respect it. We do that with an oracle: a mechanism for judging whether software behaves as intended. Many of ours use a small, independent model of what should happen. We run generated sequences of operations through both the model and the production implementation, then compare the results.

Suppose a later agent proposes a change that violates the rule. The oracle supplies a counterexample. The agent can read the model and its explanation, understand the conflict, and revise its approach.

Design can speak back.

That understanding can also deepen. A session may expose a blind spot in the oracle, an assumption that no longer holds, or a question the existing design never answered. We strengthen the model, improve what it observes, or deliberately revise the promise. The next session inherits a more developed understanding.

Closing the operational loop

Running the system gives us another way to test that understanding. We can record reliability targets, recovery requirements, and resource budgets in code, alongside the measurements and tests that assess them. If the running system misses a target, that evidence can trigger an agent investigation.

This feedback between development and operation is already central to DevOps and site reliability engineering. Agents could take on more of the work within it: investigate the discrepancy, change the system, and gather evidence of the result. The remedy might involve application code, deployment configuration, capacity, or a recovery procedure.

The agent’s task is to meet the requirement and show us the evidence. A passing test tells us about behavior under the conditions it exercises; an ongoing production requirement needs continuing observation.

An investigation can also change what we think the system should do. An incident, like a bug report or feature request, can reveal something the current design never considered. Sometimes we need to fix the system; sometimes we need to reconsider what it should promise.

Developing the intent

Building software keeps exposing us to new possibilities. An experiment can reveal a useful behavior we hadn’t imagined. A benchmark can show that an ambitious guarantee is affordable. Actual use can reveal that we have optimized something people barely notice while neglecting what frustrates them.

In “On Desire”, Venkatesh Rao asks how we come to want the goals we pursue. He describes how experience and encounters with new possibilities can change those goals. As agents make software experiments cheaper, more possibilities become worth trying.

Turning a new possibility into a commitment requires deciding what its terms mean. What counts as a completed write? Does “completed” mean accepted, visible, or durable? What does “fast” mean for that write?

Making those distinctions usable is a smaller version of the conceptual work Rao describes in “Ontological Exhaustion”: learning together to use new categories. In a codebase, we can express “completed” in a model and tie “fast” to a benchmark with a workload and a threshold.

Once we can state an idea precisely, we still need to distinguish a possibility from a commitment. The agent needs to know which ideas to explore and which guarantees its changes must preserve.

What becomes source code

We could increasingly begin a change by revising the structured intent. We would develop the design model or adjust an operating requirement, then ask agents to produce the code and deployment changes needed to realize it. The models, tests, and production measurements we maintain would help us assess the result.

Structured intent would then take on some of the role source code plays today. Production code becomes one output we generate and revise to satisfy it; deployment configuration and operating policies are others. That is what I mean by code becoming a compilation target: we work on a higher-level description of the system, while tools produce more of its implementation.

After deployment, we keep checking the running system as workloads change and new failures appear.

Building implementations from higher-level descriptions has a long history. The original FORTRAN proposal described translating concise mathematical formulations into efficient machine programs. Codd’s argument for data independence sought to protect applications from changes in how data was represented internally. Both helped establish descriptions that could survive changes in machinery beneath them.

More directly, model-driven architecture proposed generating implementations from models, using performance and other operational requirements to guide the transformation. The same ambition appears in Kiro’s approach to agent-assisted development, which centers the work on specifications.

Agents may make this approach practical for more software by lowering the cost of both implementing a design and building the instruments that assess it. A different algorithm, architecture, or deployment becomes cheaper to try against the understanding and requirements we have preserved.

Existing code and operating practices may still embody decisions we have not captured. Our checks may omit important cases or measure the wrong thing. Production experience can expose those omissions.

My programming work already revolves around understanding the system, making that understanding usable by agents, and judging the evidence they bring back. I’m interested in how much of building and operating software we can organize around that work.

Each session can leave the next agent with a deeper understanding of the system and better ways to test it. That agent can challenge and extend what we have learned. The running system becomes one realization of that understanding.

read the thread →

v2

Created: Oct 28, 2026 Most recent: Oct 28, 2026, v2

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

Btw saying you're not good as leadership is a classic humility move and makes us enlightened Losers more eager to follow you into the pits of Protocol Mount doom. Hehehe :P

from Pioneering Spirit (Blyg) ↗ · excerpt of v1

It would be if I could think of ways to actually scale and focus energy to get a lot more done. 🤔

Here I mean specifically energy level. Good leaders generally do a lot more coordination work, which typically requires an order of magnitude more communication. There’s a reason leaders are typically scheduled wall-to-wall with meetings. It really does take that much work to manage a non-trivial org. You get a few hours every week for solitary philosophizing at best, if you try really hard to create an afternoon free.

In fact one of the reasons to lead with protocol structures rather than traditional is that you accommodate lower available leadership bandwidth with more subsidiarity and decentralization. Which means you can’t steer or focus as much. In the limit, everyone is a leader/nobody is a leader. But this doesn’t mean the collective has been reduced to directionless random-walk wandering.

Matthew might want to incorporate this idea in his book.

from Venkatesh Rao's Blyg ↗ · snapshot of v1

I can do the wall-to-wall meetings of an executive but my revealed preference is clearly not doing that. Very ENTJ vs. INTJ — ENTJs want to organize the outside world and me as an INTJ can do that if necessary (helps to pretend people are systems haha) but it's a much more natural focus to be furiously organizing ideas in my head.

Being an early stage founder has been a nice fit because I get to do some of both.

Part of the reason protocols appeal to me is it feels like the right leveling up per Venkatesh's mediocrity series and fits how I like to focus on things.

My OSS work is also essentially protocol type work too — part of its long-standing appeal.

read the thread →

Created: Oct 28, 2026

Many young people now seem to think good, sophisticated writing is somehow bad because they only have seen AI write like that.

I had a 20-something year old just go through a blog post of mine labeling a bunch of very common patterns as "sounds like AI" 🤖

Created: Oct 28, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

When every week brings one or more Y2K-grade vulnerability, normal surveillance infrastructure like the CVE reporting system degenerate to uselessness. But this doesn’t mean we’re necessarily getting swamped or overwhelmed. There is no indicator that tracks the fact that AI-powered defensive reactions have also been one equally capable, possibly more so. This may not fix hardware level unpatchable vulnerabilities but for everything else, it’s not actually clear that the the threat environment has gotten worse. All we know is that our surveillance and response tracking systems are flying blind. For all we know things are getting overall more secure faster than vulnerabilities are getting discovered.

from Venkatesh Rao's Blyg ↗ · excerpt of v1

Yeah my (unmeasured) suspicion is defense is way ahead of offense. Enormous energy is being put into it and it is possible to write perfect code.

This is useful context too:

Here’s the first part of my theory: cybercriminals are not the organized geniuses we implicitly imagine. Anyone building a criminal gang has to find candidates willing to forgo more stable opportunities in the formal economy. My modeling estimated that something like 720,000 people are involved in the online criminal economy, 90% of them in scam and fraud call-center type operations, some of them human-trafficked. Of the 76k or so actual hackers, the vast majority work for governments. Of the remaining few thousand criminal hackers, most work in ransomware. Some demographic estimates of these workforces are below.

Criminal organizations need to base themselves in middle and lower income countries, where they can pay less and hire people who have few formal-economy options. For scams and fraud, picture an illegal call center building in a small city in Nigeria. For ransomware gangs, picture kids working in the informal economy in Belarus. I think folks in the AI safety and cyber world sometimes imagine adversaries as their Waluigi twins, implicit MIT graduates; in fact, in cybercrime we’re dealing with a lower-skill demographic. The chart below estimates attacker wages relative to default economy wages…

https://joshuasaxe181906.substack.com/p/if-the-vulnpocalypse-is-the-apocalypse

read the thread →

Created: Oct 26, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

LLM (linguistic computing) adoption keeps reminding me of the adoption of early computers. Talking to an LLM seems superficially much easier than using an early computer w/ programming and math etc. but both require the capacity to want to "ride the computer intelligence" with specific goals that require much more intention and dedicated focus than normal day-to-day life requires.

Which is why serious AI usage seems fairly constrained to people already used to serious intellectual work just like early computers. Most people will only use modern AI as it diffuses into normal software.

Which doesn't bode well for avoiding a big AI financial crash — a point Brad DeLong made recently, riffing on charts from Apollo's Torsten Slok. His image is a bullwhip: the tip cracks and the body moves fast, but the handle, the "S&P 493" of ordinary non-tech companies, doesn't budge. Revenue per worker and profit margins there are flat, measured productivity shows no AI boost, and mainstream firms are starting to treat token spending as a cost center rather than paying up for the latest models. That's what you'd expect if serious use is confined to people who already know how to ride their own brains. The tip of the whip is a small population doing intense, intentional work with these tools. The handle is everyone else, waiting for AI to show up inside the software they already use.

DeLong thinks the value AI does create shows up mostly as user surplus, which is real but hard for anyone to capture as profit. And even that surplus isn't nearly big enough yet to justify current valuations, because it can't scale beyond the small group riding the whip until AI diffuses into normal software and day-to-day workflows. That diffusion will come, but slowly, the way computing did. In the meantime, markets are pricing in a payoff the rest of the economy isn't yet equipped to deliver.

Why am I going on about this? Because “intelligence” in practice is not the social performance associated with “license to smart” but the demonstrated capability to “ride your brain” in some visible way.

This brings us to AI. AI is like riding a powered two-wheeler, like a motorcycle or scooter. Some people who learn to ride a bike never go on to learn to ride powered two-wheelers. You need excess regulatory capacity to manage the greater mass and velocity. This is harder than either riding a bike or driving a car.

A lot of failure to use AI effectively looks to me like bike riders struggling with two wheelers because they have acquired licenses to drive 4-wheelers.

So to adopt AI you really need to have an overdeveloped capacity to ride your own brain.

from Venkatesh Rao's Blyg ↗ · excerpt of v3

read the thread →

v2

Created: Oct 24, 2026 Most recent: Oct 24, 2026, v2

product marketing options from Mark Pincus on lennypod:

  • proven
  • better
  • new

Created: Oct 23, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

I like this — my main goal with my agent setup is basically creating a tinkering environment for thinking. Programming is now just tinkering with ideas — good ideas get compiled into code.

Just visited the Austin STEM center founded by my friend Peter Wang, cofounder of Anaconda. It’s a huge space for kids to learn robotics, maker skills etc.

The facilities are superior to what I had as an engineering undergrad 30y ago. Made me wonder if I’d have turned out very differently if I’d had that learning environment instead of a scarce environment of primitive tools.

Then it struck me, probably not. While I’m very always tinkered, I’ve always been more of an idea guy. That got me thinking: What’s the equivalent of a maker space for ideas and thoughts. What’s the FIRST robotics of thinking? Or thinkering? If traditional lab and workshop education can be transformed by imaginative redesign why not thinking experience? Why is the choice between regimented education and wandering unguided in libraries?

from Venkatesh Rao's Blyg ↗ · snapshot of v1

read the thread →

Created: Oct 23, 2026

The interesting question isn't whether we can build organizations that run without people. It's whether we can build organizations that become increasingly capable of doing things nobody previously knew how to do.

Created: Oct 21, 2026

My agents are busily doing a big refactor to part of TanStack DB when I squinted at a writeup and it looked a lot like TCP. I suggested as such and the agent said yes we actually are more or less designing this like TCP (a similar problem space queries in those ideas) and then it said "and since you bring that up, here's another cleanup that analogy suggests (collapses state) and here's a list of other well know TCP failures we can start testing against.

I just really really love coding with agents 😂

Created: Oct 21, 2026

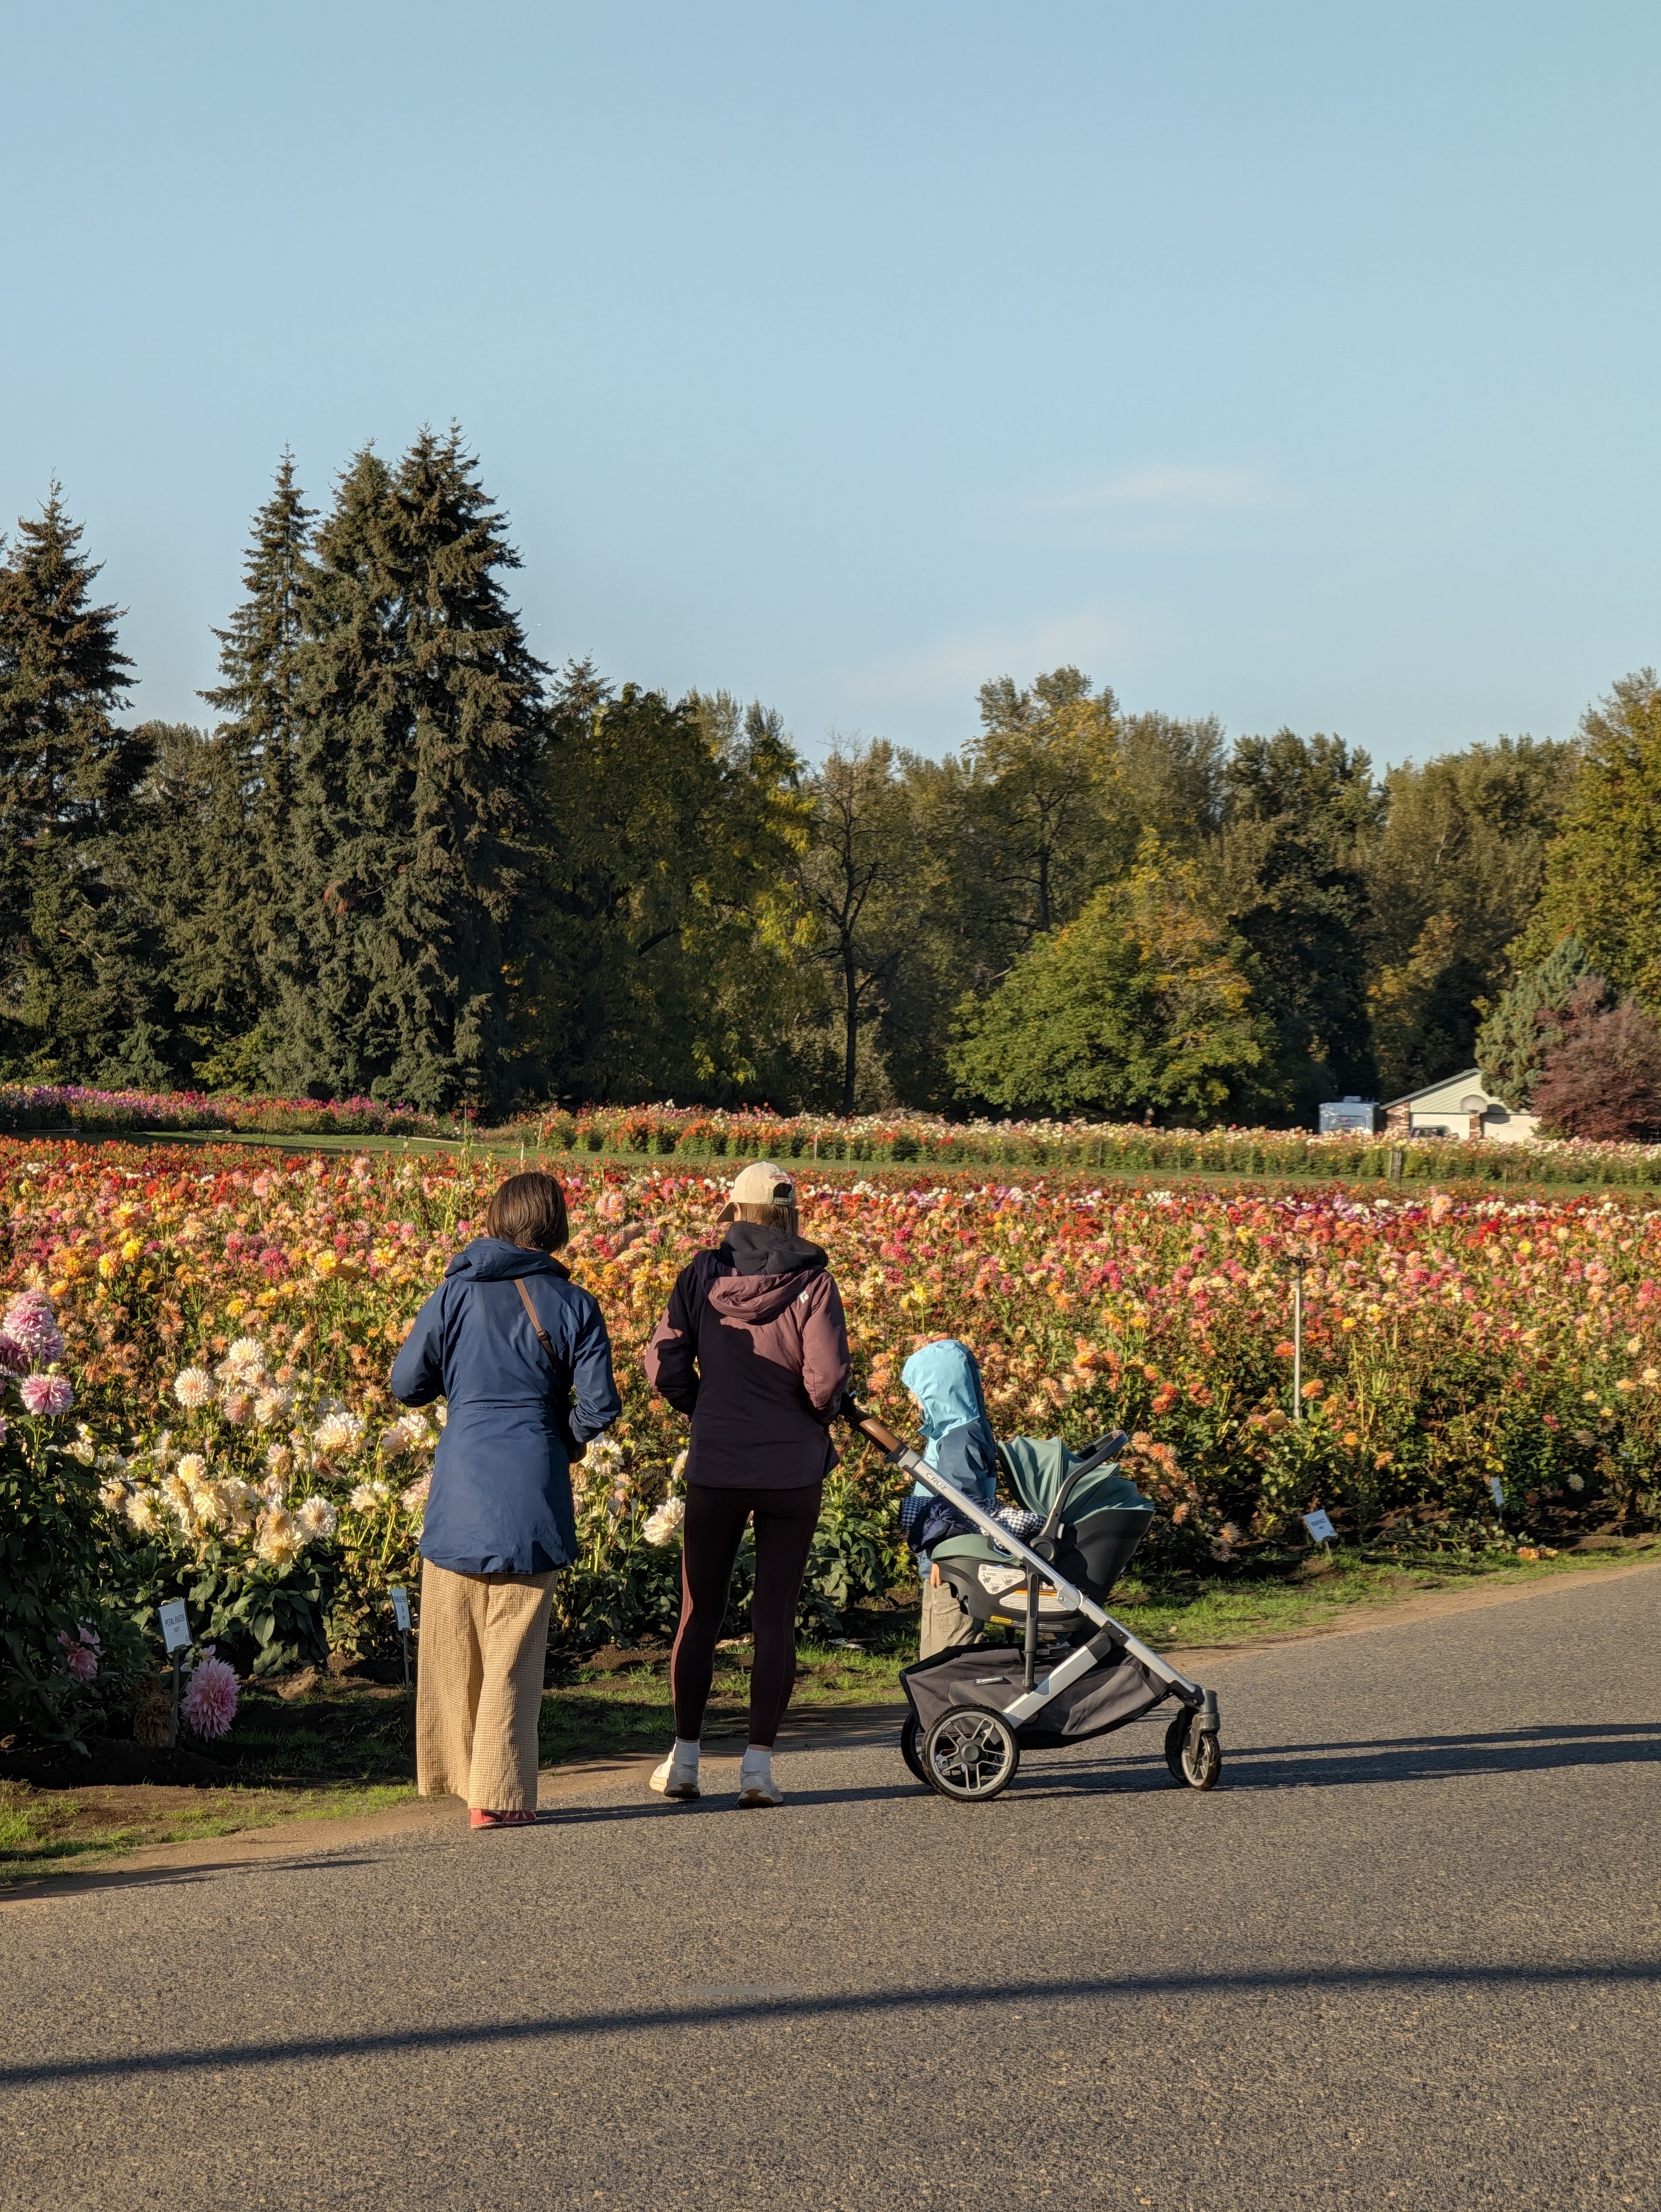
Walking around some dahlia fields near Portland on our trip.

Dahlia fields

v4

Created: Oct 20, 2026 Most recent: Oct 20, 2026, v4

thread

Can a Codebase Know Its Own Design?

Software has always needed to be precise about what it does. Computers execute our implementations deterministically. But software has historically been much less precise about what it ought to do.

Much of that knowledge lives in developers' heads: which behaviors are essential, which are accidental, which tradeoffs were deliberate, and what makes one design better than another. Tests and documentation capture some of this, but human engineers have traditionally supplied the missing judgment.

Coding agents expose the limitations of this arrangement. Every fresh session arrives without the accumulated experience of the project's maintainers. It can read the code, but the implementation doesn't necessarily tell it which behaviors are promises and which are mistakes.

This raises what I think is one of the central questions of agentic programming: How can we make a codebase capable of preserving and enforcing its own design knowledge?

Distilling design judgment

Over the past few months, I've been experimenting with an answer while preparing TanStack DB for 1.0: oracles.

An oracle is an executable model of some law the software should obey. It might express how collection change messages should behave, what a query should return, or how optimistic mutations should reconcile with authoritative server data.

Unlike a regression test that checks one reported failure, an oracle can generate thousands of variations and compare the implementation against an independent model.

The models are often remarkably simple. One of ours uses a plain JavaScript Map to predict how a collection should behave across sequences of inserts, updates, and deletes. We compare that prediction against DB's actual behavior and what a subscriber reconstructs from its change messages.

The interesting part is how these models evolve.

Agents find counterexamples that expose weaknesses in our implementation—or sometimes in the oracle itself. We investigate, clarify the underlying law, and strengthen the model. Each iteration captures another distinction we've discovered matters.

I've started thinking of this as distilling design judgment.

The investigation might involve hours of research, experiments, thought experiments, and debate. Both human reasoning and LLM reasoning are imperfect and probabilistic. But the resulting judgment can be captured as a small, precise, deterministic model.

Determinism doesn't imply completeness. These models have blind spots, and the laws themselves can be mistaken. But unlike an informal understanding that drifts between sessions, they can be systematically challenged and refined.

A conversation across generations

Christopher Alexander argued that complex design emerges through an iterative process of discovering and resolving misfits. No designer can hold all the interacting constraints of a sufficiently complicated system in their head.

Coding agents dramatically accelerate this process. An LLM is an extraordinarily fast interface to the accumulated history of software engineering. Almost every question has relevant precedents somewhere in that vast history, but finding the right ideas and fitting them together remains an iterative process.

Oracles let us preserve the results.

An agent proposes a new implementation. An oracle challenges it with a counterexample. The agent investigates, drawing on existing software designs, and proposes another solution. Sometimes we discover that the earlier law itself needs revision.

It's a conversation between different kinds of models: the LLM's broad, approximate knowledge of software; the oracle's narrow, precise knowledge of one subsystem; my own understanding of the product; and the implementation's actual behavior.

Crucially, the participants don't need to share a context window.

An agent session might spend hours improving a single oracle, exhausting much of its available context. The next session inherits the result without reconstructing the investigation. A decision made months ago can speak up precisely when a proposed change conflicts with it.

The repository accumulates design knowledge that no individual agent—or I—could possibly hold in our heads.

Evolution with executable inheritance

Daniel Dennett's account of evolution offers a useful analogy.

Biological evolution accumulates sophisticated designs through countless generations of variation and selection. Each new adaptation must compete against organisms embodying billions of years of previous improvements. Successful designs survive, providing the foundation for further adaptation.

Our agent sessions work similarly. Each proposes variations against a system shaped by hundreds of earlier design decisions. A new implementation must preserve established guarantees while perhaps fixing more bugs, running faster, or achieving the same behavior with less complexity.

Oracles make this competition unusually precise. They preserve what earlier investigations established without necessarily preserving how earlier implementations worked.

And the selection machinery itself improves. Agents discover weaknesses in our oracles, strengthen them, and leave better instruments for their successors.

Dennett calls mechanisms that make increasingly sophisticated adaptations possible cranes. Oracles are cranes: they make it cheaper to explore the enormous space of possible implementations while retaining what earlier explorations taught us.

The important achievement isn't any single oracle. It's the cumulative process.

Software that carries its own theory

This isn't entirely new. Open source has always benefited from thousands of users discovering problems that maintainers couldn't anticipate. Linus's Law captured the power of distributing that discovery across many participants.

What's changing is the speed of exploration and the fidelity with which its results can be preserved.

Users discover misfits in real applications. Agents discover more through generated experiments. LLMs help investigate solutions across the history of computing. Oracles distill the resulting judgments into executable models that constrain subsequent work.

This changes the economics of ambitious software engineering. Projects involving enormous spaces of interacting behaviors—like compiling PostgreSQL queries into reactive client collections and automatically reconciling mutations—begin to look tractable. Not because an agent can understand the entire system, but because thousands of investigations can accumulate into a coherent design without any single participant understanding the whole.

None of this eliminates human judgment. Oracles are much better at enforcing established behavioral promises than deciding which promises are worth making. The human role increasingly involves defining those boundaries, deciding which tradeoffs matter, and reconsidering the rules when exploration reveals something unexpected.

But it suggests a different answer to the debate about whether we must carefully review every line of agent-written code.

Perhaps the more important work is building an environment in which proposed implementations must survive the accumulated design judgment of everything that came before them.

Traditional programming makes the implementation executable. Agentic programming gives us an opportunity to make the design increasingly executable too.

The result isn't software that understands itself perfectly. It's software that can increasingly explain, defend, and improve its own design—even as that design grows beyond what any of its contributors could comprehend alone.

read the thread →

Created: Oct 16, 2026

In response to Summer Lightning ↗

thread · 1 quoted

Screenshot 2026-10-12 at 10.32.47 PM what if your whole personality was built in a yandex data center that is not more
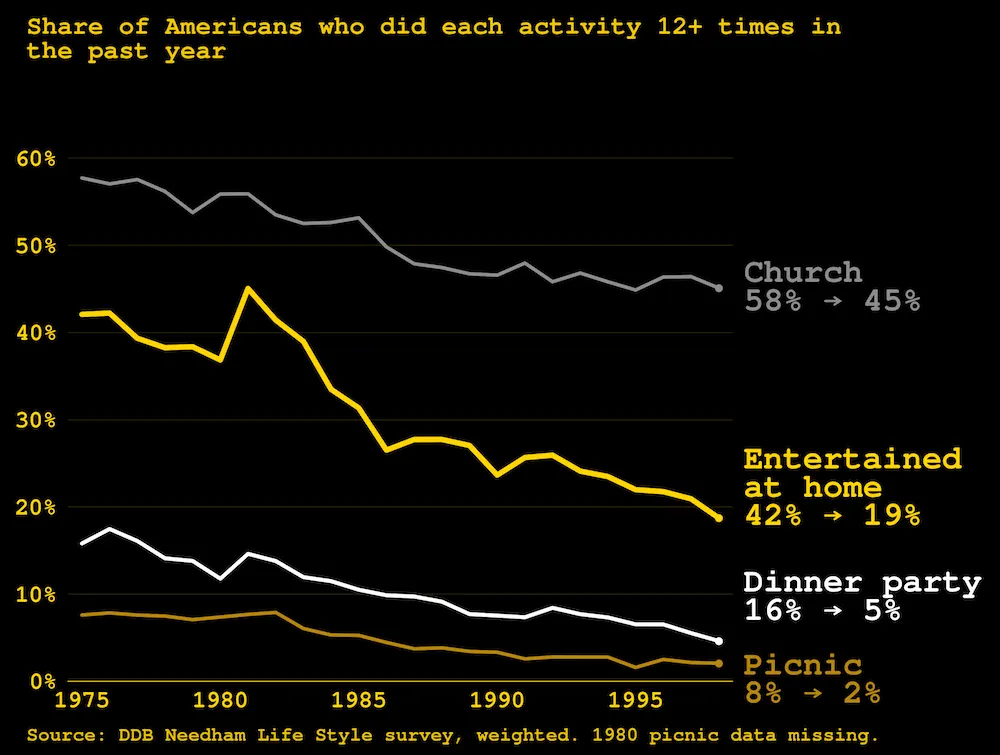
from Summer Lightning ↗ · snapshot of v1

Ukraine taking out Russias digital warfare could be in incredibly interesting (and probably beneficial) natural experiment around how modern online culture/politics actually works.

read the thread →

Created: Oct 13, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

My basic point with the original post was that time is sufficiently important to be a first-class organizing principle. I am not attached to the stream metaphor specifically but one of the motivations for blygger was putting time back into relatively atemporal information architectures like wikis and digital gardens. A governing conceit is that everything lives inside time. No eternal or atemporal objects. Kinda Buddhist transience philosophy there.

from Venkatesh Rao's Blyg ↗ · excerpt of v1

No yeah I 100% agree that time is under-theorized in social media. I was jumping off a bit from your post to a wider exploration of Blygger + gaps I see.

E.g. right now the studio is highly geared towards micro-blogging so both authoring and consuming here aren't great outside of that. So e.g. if you had an Obsidian digital garden where much of it was public and some of it was private — it'd be nice to publish that as a wiki-style thing and just occasionally to a CHANGELOG.md style report to the garden blygg for those interested. Same if you're writing a book. The GitHub analogy here is good — I follow extremely few repos on a commit by commit basis but a huge number at week to ~year timelines through tweets, changelogs, or blog posts I read.

So it seems there needs to be some sort of way to subscribe to the right layer of updates. This perhaps is just literally different Blyggs for each layer so you can subscribe to the raw change stream or a changelog or the intellectual artifact's blog (which is how repos work too).

read the thread →

v2

Created: Oct 12, 2026 Most recent: Oct 12, 2026, v2

thread

Great interview with James Carse on his book "A Religious Case Against Belief" — https://www.salon.com/2008/07/21/james_carse/


It sounds like you’re saying that belief doesn’t need to have any religious associations. You could just as well be talking about Nazism or Maoism or Serbian nationalism.

Exactly. In fact, very passionate believers are often not at all religious. However, it does happen to be the case that people who hold on to beliefs with great passion begin to describe themselves as religious. For example, the Nazis had a kind of pseudo-religious understanding of themselves. Hitler talked about a 10,000-year Reich. That’s taken right out of Christian mythology — the kingdom of God going on forever and ever. The swastika is, after all, in the form of the cross. So Hitler was a passionate believer — not religious but pseudo-religious — ascribing to himself some sort of religious aura.

So what is it that holds together a belief system?

A belief system is meant to be a comprehensive network of ideas about what one thinks is absolutely real and true. Within that system, everything is adequately explained and perfectly reasonable. You know exactly how far to go with your beliefs and when to stop your thinking. A belief system is defined by an absolute authority. The authority can be a text or an institution or a person. So it’s very important to understand a belief system as independent of religion. After all, Marxism and Nazism were two of the most powerful belief systems ever.

What, then, do you mean by religion?

Religion is notoriously difficult to define. Modern scholars have almost unanimously decided that there is no generalization that applies to all the great living religions. Jews don’t have a priesthood. Catholics do. The prayer in one tradition is different from another. The literature and the texts are radically different from each other. So it leaves us with the question: Is there any generalization one could make about religion?

You’re also suggesting that there’s no underlying unity that permeates all religions, that, in fact, they’re totally different from each other.

I’m absolutely saying that. There have been a lot of fantasies about putting all the religions together. Mahatma Gandhi was famous for saying that all religions are, at their core, the same. But I have spent my life studying these traditions. I am a historian of religion. And the more I studied them, the more I saw that they were absolutely different.

And yet, you’ve just told me that you yourself don’t believe in a divine reality. In some ways, your critique of belief systems seems to go along with what the new atheists are saying.

The difference, though, is that I wouldn’t call myself an atheist. To be an atheist is not to be stunned by the mystery of things or to walk around in wonder about the universe. That’s a mode of being that has nothing to do with belief. So I have very little in common with them. As a matter of fact, one reason I wrote the book is that a much more compelling critique of belief systems comes not from the scientific side but from the religious side. When you look at belief systems from a religious perspective, what’s exposed is how limited they are, how deeply authoritarian they are, how rationalistic and comprehensive they claim to be, but at the same time how little staying power they have with the human imagination. It’s a deeper and much more incisive critique.

Why are you so pessimistic?

Let’s look at Islam, as an example. There’s no way of reducing Islam to a single belief system, but what you have in Islam is a very active series of belief systems. And they’re in deep conflict with each other. There’s no poetry in this. It’s all strictly hard belief, in an oppositional voice. But if you go back in Islamic history, what you get is a very deep sense of poetry. As a matter of fact, the Quran itself is considered so poetically beautiful that it’s a very high value in Islamic life to memorize it and sing it. Muslims refer to the Quran as a recitation, something to be repeated over and over again.

You go back to the medieval mystical period and you find Islamic thinkers who say terribly beautiful things. There’s a story told about Abu Ali of Sind, a famous mystic. He made his annual trip across the desert, which took days, to get his supplies in the markets on the other end of the desert. Then he walked all the way back, opened the packages that he bought and found that there were ants in his cardamom seeds. Immediately, he wrapped the ants back up in the cardamom seeds, walked back across the desert and returned the ants to their home. That’s a different Islam. That’s a poetic Islam. It comes right out of the heart of that religion.

read the thread →

Created: Oct 12, 2026

In response to Mike Casey's blyg ↗

thread · 1 quoted

Things that make you go 🤔

9 October // a16z leads $870 million Series A for TypeSafe AI (Jev) at a $7.5bn valuation

Also 9 October // Microsoft introduces Decision-1 with higher accuracy and lower latency than Jev

from Mike Casey's blyg ↗ · snapshot of v4

Typesafe is already at $100m ARR is what was leaked. Investors and customers are probably comfortable betting the inventors of a new category will continue to out innovate fast followers.

read the thread →

v2

Created: Oct 11, 2026 Most recent: Oct 11, 2026, v2

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

I wonder if this is a bit too pinned (ha) to the stream metaphor.

The underlying problem seems to be that we're trying to represent a collection of persistent, evolving intellectual objects through an interface originally designed to display publication events.

Wikis solved a version of this problem decades ago by separating three things:

  1. Activity: What changed recently? (Recent Changes, watchlists, notifications)
  2. Landscape: What exists, and how is it organized? (Pages, indexes, categories, links)
  3. History: How did this object develop? (Revisions, provenance, relationships)

These are three different questions that needn't be collapsed into one sorting function. A change to a Wikipedia article produces an event in Recent Changes; it doesn't move the article somewhere else in the encyclopedia.

I think Jyri Engeström's social object theory provides a useful broader perspective. Successful social software tends to organize around objects that people have independent reasons to interact with. GitHub is useful to a single developer pushing code to a repository. Flickr was useful simply for organizing photographs. The social features supercharge activities that already have value.

This suggests a useful progression for Blygger:

One author: A commonplace book, something like Roam, for developing an interconnected body of ideas over time. Fragments, revisions, links, transclusions, and collections are already useful without an audience.

Two authors: A correspondence. You develop ideas in conversation, incorporating and challenging each other's arguments. The correspondence itself becomes a persistent intellectual artifact.

Many authors: Something resembling the historical Republic of Letters, with ideas circulating, recombining, and developing across a decentralized network.

The basic test is whether Blygger is genuinely useful at the first stage. GitHub didn't have to invent a reason for people to interact with repositories; the repositories were already useful. The social network grew around the work.

This also makes me wonder whether we're looking for too much uniformity in the interface. Different activities naturally suggest different metaphors, both for authoring and consuming:

  • Roam or a digital garden for accumulating and connecting fragments.
  • GitHub repositories for larger composed works like essays, books, or research projects, with histories, forks, and releases.
  • Wikis and libraries for navigating persistent bodies of knowledge.
  • Feeds and inboxes for discovering activity and changes.
  • Correspondence for following intellectual exchanges between authors.

Of course, supporting different views over the same underlying objects is already fundamental to Blygger's protocol design. That's precisely what makes exploring these different interfaces so interesting. We don't need to find one metaphor that does everything.

In particular, I'm not sure substantiality needs to determine where an object lives. A book doesn't become more prominent in a library every time someone revises it. Pins establish durable references, while revisions create events that might be interesting to subscribers. The object's persistent identity and its activity are separate concerns.

Perhaps the broader opportunity is to make evolving intellectual work into a first-class social object, rather than making a better feed of posts about intellectual work.

The feed is then one window onto that world, not the world itself. And the interesting design space is all the different ways authors and readers might inhabit that world.

Inertial feeds, feed pinning, pace-layered feeds

Just realized a basic problem. The authoring interface is both diachronic and synchronic, but the published surface is pure synchronic. We need a sort order that’s the diachronic equivalent of “reverse chronological” without being “algorithmic” (ie an order that’s not derived from semantics or subjective preferences). There are 3 variables available: number of versions, number of pins, depth of transclusions, possibly with versions and pins recursively accounted for. This gives an item a “weight” of “substantiality”. So the order is “descending weight” where weight = sum(pin-weighted version count*+discount*(sum(pin-weighted version count of all transcludes)).

Does this make sense?

This also solves the “book blyg” problem without need for a whole new client. You’d do this with a thread of threads that’s essentially a book where every chapter thread has gone through multiple versions, and many versions are pinned. This would score very heavy-weight in this scheme.

There aren’t that many parameters here so we could expose them in the settings as tuning knobs, and also have a checkbox for picking whether the default view should be reverse chronological or descending weight.

But the big idea: We can also think of blending by using the weight to determine how quickly the item flows down in the feed. The heavier it is, the stickier it gets. An item that’s been versioned 50 times and each is pinned will essentially be an immobile rock at the top of the feed, ie reproduce the “pinned items” behavior in trad feeds. Here there’s a slight issue. If the stream metaphor is generally understood as a top-down view, the weight-settling direction is into the stream. If it’s understood as front-on, like a waterfall, heavier weights should sink faster. I’m inclined to ignore this ambiguity since the “pin” metaphor already

Just realized: If you treat pins as depth you can just do pace-layering. And versions should basically be a “swim upstream one tick” event

from Venkatesh Rao's Blyg ↗ · snapshot of v2

read the thread →

Created: Oct 11, 2026

We've discovered linguistic computing, but we're still trying to understand it using theories about artificial people, when the more relevant intellectual traditions might be the study of media, institutions, and the evolution of complex systems.

Created: Oct 9, 2026

The great irony is that AI-doom proponents imagine themselves as the people taking the radical implications of AI most seriously. Yet by insisting on understanding AI through the familiar story of an artificial person becoming extraordinarily powerful, they may be among the people most constrained by inherited categories.

Created: Oct 9, 2026

In response to simonwillison.net ↗

thread

We're living in interesting times indeed

Quoting Matthew Green

Everyone is very concerned about being respectable, so I’m going to be the goofball who raises worst-case possibilities. I think there is a 1% chance we live in Minicrypt, and a 15% chance we functionally lose confidence in our existing public-key encryption algorithms. [...]

The problem here is that the speed of AI producing surprises, and the speed of human beings replacing standards (even with the very best AI assistance) are just orders of magnitude different. You only recover from a surprise like this if you do the preparation in advance.

— Matthew Green , on Twitter. I looked it up and Minicrypt is Russell Impagliazzo’s hypothetical world in which public-key encryption is impossible.

read the thread →

Created: Oct 9, 2026

AI makes intelligence abundant. Great software comes from turning that abundance into better search, better selection, and better accumulated theory—not simply more code.

Created: Oct 8, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

Random thought: AI has put to rest the idea that ideas are nothing and execution is everything given how little impact the huge number of new vibe coded have had. It seems clear picking the right problem to work on and when was and remains a first class entrepreneurial skill.

from blyg.bricolage.io ↗ · snapshot of v1

To some extent this had always been true because failures are invisible even in the home industry after a while. Survivorship bias. I bet young techies under 18 wouldn’t get Juicero or color.com or webvan or google wave references.

And every industry is littered with these.

What AI changes is the scale, n=1 persistence, and aggregate visibility. One guy using a custom task manager is invisible (I recall you had a GTD app long ago). But a million people with custom to-do apps is an event.

AI makes low-novelty 0 to 1 dirt cheap and a solo thing for many categories. Getting to n=2 is now the challenge. A bit like novels where they say the second novel is the test. Except n is users as well as products.

Macro protocols (ie not like hand-washing) fundamentally operate in the n>1 regime since they make no sense at n=1, and having compounding “variability resistance” as adoption grows because the cost of breaking changes is network loss.

There’s a kind of herd immunity to the divergence effects of AI which naturally drives variety through cheapness of experimental implementations.

from Venkatesh Rao's Blyg ↗ · snapshot of v1

I researched a while ago all the main schools of thought on startup strategy/timing/etc to see how AI affected them and was surprised that basically nothing has changed.

Very few startup problems were ever gated primarily by implementation costs. The hard parts have always been figuring out what to build, getting scarce, high-quality feedback from reality, and achieving adoption.

AI dramatically accelerates the idea → artifact loop, but does much less for the artifact → consequence → observation → learning loop.

Reality has latency.

You still have to wait for people to encounter your product, try it, incorporate it into their workflows, discover what annoys them, decide whether to pay, recommend it to colleagues, or quietly abandon it.

Much of this feedback is intrinsically time-bound. You can't discover whether something becomes part of someone's weekly routine in an afternoon. You can't parallelize your way to years of institutional trust.

This creates an interesting paradox: as AI makes building faster, patience and experimental discipline become more valuable.

You can generate 500 product changes while reality has only produced one new bit of evidence. The danger is massively over-updating between observations—overfitting to an information-starved environment.

So perhaps AI's biggest effect on startups isn't removing the old bottlenecks, but making them dramatically more visible. When generating possibilities becomes nearly free, the scarce resource is contact with reality.

And reality is slow.

read the thread →

Created: Oct 7, 2026

Random thought: AI has put to rest the idea that ideas are nothing and execution is everything given how little impact the huge number of new vibe coded have had. It seems clear picking the right problem to work on and when was and remains a first class entrepreneurial skill.

Created: Oct 7, 2026

thread

1/ Programming has a strange relationship to nature.

At the bottom, we’re stuck with hard constraints: computability, information theory, memory, latency, the speed of light, heat, hardware failure.

These are not negotiable. We discover them.

But software also lets us create new effective laws almost at will.

2/ A filesystem says these bits are a file, files have names, directories contain files, bytes persist after a process exits.

A database says a transaction is atomic—even though underneath, hundreds of fallible physical operations happen over time.

A language invents objects, types, promises, ownership.

None of these things exist in physics. We made them up.

And then something curious happens: once we make them up, we have to start discovering their consequences.

3/ Humans invented the rules of chess, but we didn’t invent the fact that some position is mate in seven.

Once the rules exist, objective facts about that world follow from them.

Software is like this everywhere.

We choose transaction semantics and discover anomalies. We invent a rendering model and discover what identity must mean inside it. We define a protocol and discover behaviors nobody explicitly designed, but which follow inevitably from its rules.

At the layer where you create an abstraction, you’re a legislator.

One layer above, you’re a physicist.

4/ This is what makes abstractions so powerful: they don’t merely save code. They refactor reality for everything above them.

Once the machinery is reliable enough, the upper layer stops seeing the mess below. It inhabits a simpler world with different apparent laws.

Venkatesh Rao’s “New Nature” is useful here: technology accumulates artificial lawfulness until it becomes part of the environment itself.

Programmers do this recursively, at tiny scales, every day.

5/ Dennett’s idea of “cranes” explains how these worlds accumulate.

Evolution doesn’t start from scratch. Once it discovers a useful mechanism, that mechanism becomes part of the platform from which further complexity can emerge.

Software abstractions do the same.

Filesystems, databases, protocols, type systems, frameworks: each packages previous discoveries into structure that future systems simply assume.

A framework isn’t merely reusable code.

It’s reusable theory—accumulated search the next program doesn’t have to repeat.

6/ So there’s a recursive process:

discovery → theory → mechanism → law → nature → new discovery

We discover something about a world. We encode the discovery into an abstraction. The abstraction becomes part of the environment. The next programmer encounters our invention as nature and starts discovering its laws in turn.

Software is, in this sense, recursive nature-making.

read the thread →

Created: Oct 6, 2026

In response to Aneesh's Blyg ↗

thread · 1 quoted

Terrible advice cause I would just buy nice jackets and go for walks, and may be write a few things here and there (this is roughly what I'm doing now)

The best longevity protocol is to live like someone who isn’t worried about money.

from www.msweet.net ↗ · snapshot of v1

from Summer Lightning ↗ · snapshot of v1

The one thing about San Diego is the dearth of jacket wearing opportunities. I really like a good jacket… something something twiggy arms

from Aneesh's Blyg ↗ · snapshot of v1

My favorite part of living in the bay area — the whole year was jacket weather (in the morning/evening at least)!

read the thread →

Created: Oct 6, 2026

In response to Aneesh's Blyg ↗

thread · 1 quoted

green tests prove the code agrees with its mocks

from Venkatesh Rao's Blyg ↗ · excerpt of v1

As a non-software dev software person, i have never understood the purpose of mocks.

from And Yet Here We Are 🚀 ↗ · snapshot of v1

They suck unless you really need them — generally you really need them if the thing you're mocking is too expensive or slow to run or impossible to run e.g. a 3rd party API that doesn't have a test environment.

from blyg.bricolage.io ↗ · snapshot of v1

That’s interesting, years ago I had asked a cousin of mine who was into automobile engineering why they had to run the whole car to test a new chip. He said that they needed to get the actual signals and they mock signals just aren’t good enough.

Didn’t go deeper into it, but it’s funny that a car should be easier to not build mocks for than code.

from Aneesh's Blyg ↗ · snapshot of v1

Probably because the physical world have far more variation than the digital world. Many digital things are pretty simple & deterministic so easy to mock. Mocks can still bite you so people still advise to avoid them when possible but they're often just fine.

read the thread →

Created: Oct 6, 2026

In response to Aneesh's Blyg ↗

thread · 1 quoted

green tests prove the code agrees with its mocks

from Venkatesh Rao's Blyg ↗ · excerpt of v1

As a non-software dev software person, i have never understood the purpose of mocks.

from Aneesh's Blyg ↗ · snapshot of v1

They suck unless you really need them — generally you really need them if the thing you're mocking is too expensive or slow to run or impossible to run e.g. a 3rd party API that doesn't have a test environment or a payment provider that would charge real money every run, anything that sends real emails or SMS to actual people, hardware you don't have on your dev machine (a printer, a GPU cluster, some IoT device), a huge ML model that takes minutes just to load, or nondeterministic stuff like the current time or randomness that you need to pin down to get a repeatable test.

read the thread →

v2

Created: Oct 6, 2026 Most recent: Oct 6, 2026, v2

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

I pointed Venkat's post to ChatGPT and asked it to reflect on its limitations as a Large Language Model:

Rao’s argument points to a real limitation of Large Language Models: language is a powerful representation of thought, but it is not thought itself.

Humans often reason in forms that are only partly linguistic—spatial intuition, diagrams, motor skill, rhythm, visual pattern, physical feel, mathematical structure. The prose comes afterward, as a compressed rendering of a richer internal process. If that is true, LLMs are naturally strongest on problems whose structure survives being turned into language, and weaker where the important knowledge is tacit, embodied, spatial, or perceptual.

There is also a training-data bias. Much human expertise never gets fully written down. A machinist, surgeon, athlete, cook, or gardener may know thousands of fine-grained things they cannot easily articulate. LLMs mostly inherit the subset of human knowledge that made it through the linguistic bottleneck.

The nastiest failure mode is therefore confusing articulate explanation with actual understanding. An LLM can produce a beautifully coherent verbal model even when the underlying model is thin.

But “language model” may ultimately be a misleading name. Modern systems increasingly work with images, audio, tools, environments, and other nonlinguistic representations. The deeper limitation is not necessarily that AI is made of language, but that its contact with reality has mostly been mediated through artifacts humans encoded.

Humans learn by pushing, seeing, hearing, building, failing, and inhabiting the world. LLMs largely inherit the residue those experiences left behind.

Critical thinking is multimodal. Visual, mathematical, mechanical, even musical… there are many. Howard Gardner had a theory of multiple intelligences. And though the case for Goleman’s “emotional intelligence” is much weaker, there is something there too. None dominant generally in all situations. This is why the shape rotators vs. wordcel meme took off. I don’t like STEM-supremacism either, but it was much-needed pushback on the bs theory that critical thinking = writing.

from Venkatesh Rao's Blyg ↗ · excerpt of v2

read the thread →

Created: Oct 2, 2026

I've done 83 PRs in the past week on TanStack DB. I'm clearing out all known bugs for its 1.0. A very strong week in the past pre ai might have 30-40? https://github.com/TanStack/db/pulse?period=weekly

AI gives you a strong sense of time dilation. A day feels like a week: you make so many decisions and see so much that it's like a whirlwind vacation, five cities in four days. We're all celebrities hopping private jets now, work wise anyways.

v2

Created: Oct 1, 2026 Most recent: Oct 1, 2026, v2

Forked from Venkatesh Rao's Blyg ↗

thread

Ok here's a few:

  1. Any sufficiently advanced work is indistinguishable from play
  2. Any sufficiently advanced domain is indistinguishable from any other
  3. Any sufficiently advanced haircut is indistinguishable from general neglect

Snowclone Fork Challenge

Maybe VGR, as the instigator and ringleader of the nascent Blygger movement, should start throwing out some challenges? That can all help us get to know each other’s vibe?

Here’s a simple challenge that I think might be a fun way to get a feel for pins and forks. Write a pithy aphorism with a challenge to people to make a snowclone of it, and pin at least 1 version. Then people can fork the pin, edit suitably, and pin their own version, allowing more forks and pins.

Worked example:

  1. Any sufficiently advanced technology is indistinguishable from magic (Clarke)
  2. Any sufficiently advanced technology is indistinguishable from nature (Karl Schroeder)
  3. Any sufficiently advanced technology is indistinguishable from play (Seb Paquet)

read the thread →

v2

Created: Sep 30, 2026 Most recent: Oct 4, 2026, v2

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

Hmm this is interesting. We grow a lot of vegetables and I do mainly like recipes that show off the rich flavor of home-grown food.

On an iron chef episode, I learned of a philosophy of cooking called the Rosanjin school. where you do as little as possible to modify the taste of an ingredient and do your best to bring out its natural character. The featured ingredient was mayatake mushrooms and the Rosanjin school guy beat the iron chef Japanese. I think this is my philosophy of AI writing. Let the model’s terroir shine through. Which is weird since I mainly cook Indian and Indian food is mostly the opposite philosophy: Beat the ingredients into submission and overpower them with spices. Resistance is futile.

Kitaoji Rosanjin was a potter and calligrapher before he was a cook, which maybe explains it. His line was that ingredients are ninety percent of the dish and the cook is the remaining ten, and that a plate is the kimono the food wears. Mostly he just got out of the way.

from Venkatesh Rao's Blyg ↗ · snapshot of v1

read the thread →

Created: Oct 1, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

Whatever it is it's pretty mysterious how parents can pluck emerging popular names out the air. I've had several friends who deliberately tried to pick uncommon names yet somehow the name they picked shot up into the top ten that year.

Precommodification followed by a virtuous salience cycle? Perhaps seeded by a famous Kyle in a previous generation?

My name was from someone my parents met at Disneyland yet "Kyle" still peaked as a name around when I was born 🤔

from blyg.bricolage.io ↗ · excerpt of v1

from Venkatesh Rao's Blyg ↗ · snapshot of v1

read the thread →

Created: Sep 30, 2026

In response to Brady Dale's blyg ↗

thread · 1 quoted

Yeah my wife and I spend a fair bit of effort trying to make friends. It is remarkable how resistant many people are, immediate shutdown. And very noticable when someone is willing to open up a bit and allow repeated encounters etc. One of my guesses is that most people are poorly equipped for any divergences in people around them. They like very homogeneous social groups. So the great divergence happening where everyone is getting more and more different from each other has really weirded them out.

The death of hanging out

Derek Thompson has a new post in his newsletter about how no one is having dinner parties any longer. 

There’s lots of stats about how badly social life has collapsed in America. You can click on the link to see them. It’s bad.

from bradydale.com ↗ · snapshot of v1

From my own experience: I live in a very small town. One of my oldest friends lives across the street. I could throw a baseball to his house. We do get together roughly every week or two, usually with another friend. So that’s good. But we never stop by each other’s place. Even though we are both just right there. It just doesn’t feel right. 

And I think that speaks to the larger unease we all have with, I suppose, imposing on each other. We all err on the side of staying out of each other’s hair.

from bradydale.com ↗ · snapshot of v1

One small part of his post jumped out at me: the fact that we are exercising more but we also tend to do that alone.  Maybe I just recognize myself in this, as a longterm gym denizen? But I think it points to something deep about this reluctance to get to know each other.

He writes:

As I wrote in an essay last year on the “great American exercise boom,” the evidence suggests that, despite the increase in running clubs, the surge in exercise time seems to be mostly solo. A lot of people are going to the gym with a podcast to keep them company (e.g., me) or rolling out a yoga mat in the basement by herself (e.g., my wife).

from bradydale.com ↗ · snapshot of v1

If you go to the gym, you have probably noticed that hardly anyone ever talks to anyone there. It is very weird to talk to strangers at the gym.

In the gym I’ve gone to here in small town America, there is a clique in there that chats a lot, but most people don’t. This is strange to me, because those of us who go are so unusual here. We’re all in decent shape! That is very counter-cultural in the Midwest! You’d think we’d bond over being such local freaks! But we don’t. 

We keep to ourselves.

Even in group exercise is alienated. You might do the same class every weeks for months, but will you ever learn the names of the people you do the class with? In my experience, probably not. I’ve logged an unbelievable number of hours in group exercise, but I have seldom made any friends there.

You might just say: Well, you’re a weird guy Brady. True. But I also didn’t see it happening between others. People didn’t talk to each other much. They just came in, did the thing, and left. 

from bradydale.com ↗ · snapshot of v1

Folks just aren’t bridging the stranger gap to get to know each other. 

Even when we do gather in a room together, do a thing we share as a common interest, on a regular basis, week after week, we don’t get to know each other along the way. 

That’s a little unsettling.

from bradydale.com ↗ · snapshot of v1

What bothers me the most is that I have no idea what anyone could do about it. It seems to me that all of this speaks to a very deeply-rooted rot in our culture. 

from bradydale.com ↗ · snapshot of v1

—Brady Dale
September 30, 2026

from Brady Dale's blyg ↗ · snapshot of v2

read the thread →

Created: Sep 30, 2026

In response to Sachin Benny ↗

thread · 1 quoted

My first name "sachin" is probably the most pre-commodified name in India from the mid 90s when cricket player Sachin Tendulkar was a household name. I think my parents literally could not figure out what to name me and just went with something that was in the air

Precommodified last names + nominative determinism

X thread on papers by people with the same last names

An abundance of Katherines paper

A Few Goodmen paper

from Venkatesh Rao's Blyg ↗ · snapshot of v2

from Sachin Benny ↗ · snapshot of v1

My name was from someone my parents met at Disneyland yet "Kyle" still peaked as a name around when I was born 🤔

read the thread →

Created: Sep 29, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

Yeah seems like "blig" https://youglish.com/pronounce/blyg/swedish

How is everyone pronouncing ‘Blyg’?

I’m going ‘Bligh’ but I suppose ‘Bliegh’ is an alternative?

Whatever we name the collective Blygs the people will be Blyggeratti

from And Yet Here We Are 🚀 ↗ · snapshot of v1

I don’t know how the Swedish word is pronounced but I’m going with blig

from Venkatesh Rao's Blyg ↗ · snapshot of v1

read the thread →

Created: Sep 29, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

Amara’s Law is that people overestimate a technology in the short term and underestimate it in the long term.

I think AI is radically violating this pattern. What’s happening instead is that in the short term, people are wildly overestimating entirely fictional aspects and utterly wildly underestimating the very real nonfictional things.

As for the long term nobody is actually estimating them at all due to the really bad premature ontologies.

Most people have no idea what’s about to hit them, though some have some sense of how hard it’s going to hit.

They’re using unimaginably lazy answers to the what, so even if they get the order of magnitude right on how hard, it doesn’t help.

“AGI” as an idea is an ontological high crime here.

from Venkatesh Rao's Blyg ↗ · snapshot of v1

Yeah AI reminds me of early internet discourse 90s/2000s where everyone was gung ho about the internet but there'd be this occasional blog post with a dark prophecy about how the internet would destabilize everything ala printing press. Which seemed dark and distant but hey, guess what happened... AI is still in that honeymoon period where it's all fun and games (well for me — obviously a lot of people are freaking out already) but the destabilizing effects are starting to come in, much faster than they did with the internet which needed a whole slew of social media properties to be invented and go mass market. ChatGPT is already at 1B+ so the destabilizing aspects are already hitting an already destabilized society.

All that being said, I far prefer life w/ the internet than without and AI seems the same but all the same, it'll be a ride for the next few decades as all this plays out.

read the thread →

Created: Sep 29, 2026

In response to Brady Dale's blyg ↗

thread · 1 quoted

Yeah there's multiple layers here all named "Blyg" — the underlying protocol up the Venkat's envisioned new style of blogging/tweeting — if you're using Blyg the protocol but basically just "blogging" still then you're a blogger and part of the blogosphere (to the degree that still exists). But if Blyging becomes a genuine new medium then it deserves its own name. Potentially though Blyg the protocol could birth other mediums just like RSS helped enable Podcasting.

What’s the best name for the community of blyg users?

by Kyle Mathews · quoted from v1

What should we call the network of blygs? Call for stub commentary towards a rough consensus, not a voting exercise.

Probably a minority take, but I think the best term for people who use Blygger is just: bloggers.

Blygger is a useful update to blogging. It extends blogging, but it’s not separate.

Update: Looks like I was quoting a quote. Original question here. Anyway, we’re still in the blogosphere, if you ask me. 

from bradydale.com ↗ · snapshot of v1

—Brady Dale
September 29, 2026

from Brady Dale's blyg ↗ · snapshot of v2

read the thread →

Created: Sep 29, 2026

thread

I designed a new small feature for TanStack DB yesterday and I thought it was a nice snapshot of where I/we are at with AI-enhanced software design. My process is dramatically different and faster than it was pre-ai. Coming up with something this sophisticated would have taken a lot more research/prototyping time in the past.

With my Field Lab skill, I've moved deeply into structured analysis (with what I call "linguistic algorithms") which I find very satisfactory and I think the results are much better than what I used to get.

The process of coming up with this took maybe 20-30 minutes of active time and ~3 hours of agent time.

https://github.com/TanStack/db/issues/1935

I had the agent write up a summary of what we did


How we got to this design

We started from a real app's hand-built subscription manager and asked what TanStack DB should provide instead. We didn't go straight to an API. We ran a series of structured steps. Each one looked at the problem in a different way and checked the step before it.

  1. Survey. We looked at how other libraries and apps tie live event channels to cached query data. We noted what they get right and where they break.

  2. Lifecycle model. We described the problem as a short list of states and actions: acquire, release, fetch, event, evict and cleanup. Then we generated many orderings of those actions. This found edge cases that are easy to miss by hand, such as an event arriving while a fetch is in flight, or a user leaving during a fetch.

  3. Candidate designs. We combined the findings into full designs over three rounds. After each round we checked that nothing had been dropped and that no two parts contradicted each other. We then wrote four different candidate designs and compared them side by side.

  4. Decisions. Kyle chose among the options:

    • Events can write rows directly.
    • A channel lives exactly as long as its Query stays in the cache (gcTime), with no separate setting.
    • Sharing one socket among many listeners is the app's job, not the library's.
    • Refetch hints are a supported option, with debouncing.
  5. Stress test of the chosen design. We wrote the design's rules down and tried to break them with hostile cases, such as late events, stale fetches, and rows shared by two subsets. Each break either changed a rule or became a documented limit.

  6. Formal model (TLA+). We encoded the design and had a model checker try every ordering of events for two subsets that share a row. It found four rules the design needs:

    • an event marks every Query that holds the row as out of date, including cached ones;
    • on a shared row, the newer fetch wins;
    • a direct write to a shared row makes the other subset refetch;
    • the first fetch waits until the server confirms the subscription.

    To show the model can catch real mistakes, we also removed each safeguard in turn and checked that the model then reported the matching failure. The model also found a race that exists in TanStack DB today, with no subscriptions involved.

  7. Final check against the original. We compared the draft issue with the original manager's code line by line. This recovered cases the draft had dropped and fixed contradictions before we published.

The result is issue #1935. It includes the formal model, which can serve as the starting point for the test suite when the feature is built.

read the thread →

Created: Sep 29, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

Blyggerstan, Blyggerville, Blyggerton, Blygernia, Blygernania 😜

Blygosphere wins for continuity.

What should we call the network of blygs? Call for stub commentary towards a rough consensus, not a voting exercise. Two main options I think are:

  1. Blyggersphere
  2. Blygosphere

I like the first one, but suspect the second one will have a strong memetic advantage.

from Venkatesh Rao's Blyg ↗ · snapshot of v1

read the thread →

Created: Sep 29, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

🫡

Blygger update

Did a lot of work today on blygger.

Spec

  1. Finished bringing reference client up to full 0.3 compliance and froze v 0.3. People building production clients should build against this.
  2. Wrote the living v 0.4 spec. People who want to help test the unfrozen spec can build against this. It’s a moving target that gets revised as the reference client implementation finds issues.

Reference client, now named Blygger Studio

  1. Lots of work, mostly invisible.
  2. There is now an update alert mechanism that alerts users about new version
  3. There is a packaged templated version with deployment instructions

Backend

  1. Spec and ref client are now separate repos
  2. Issue pipelines now exist. You can file issues against either the spec or the reference client. Let your agent decide which.
  3. Several technical notes for stuff the protocol will remain agnostic about, but are features people want to build, are cued up and will be published in the next couple of days

Sites

  1. All queued new blygs approved on blygger.com
  2. Blygger.org has updated documentation and the newly frozen v0.3 specs\

from Venkatesh Rao's Blyg ↗ · snapshot of v1

read the thread →

Created: Sep 28, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

Please don’t name your blyg just blyg. Call it something like John Doe’s blyg if you can’t think of a creative name. Otherwise the reading feed is very confusing. Please stub this far and wide to propagate this norm. I’ll make the reference client pick better personalized default names but I can’t control what other clients do.

from Venkatesh Rao's Blyg ↗ · snapshot of v2

read the thread →

Created: Sep 28, 2026

In response to Protocol Institute Blyg ↗

thread · 1 quoted

From a ChatGPT chat re starship reaching orbit. Deserves congrats but qualified congrats relative to original rhetoric.

As an aside, I need to add an import case to the generated text span markup in the blygger spec. Probably just something like [tk] impyrt = cut and paste[/tk] would do. —-

The compact version is that V3 gets Starship much closer to being a practical heavy-lift rocket, but the original extreme economics remain almost entirely an operational-reuse hypothesis rather than something V3 itself demonstrates.

The notable points:

  • V3 attacks mass fraction hard. Raptor 3 has more thrust (250 tf vs. 230 tf sea-level), lower installed mass, integrated plumbing/thermal protection, fewer external components, and less shielding. Super Heavy similarly integrates the hot-stage structure and simplifies the grid-fin system.
  • Ship is bigger and carries more propellant. SpaceX now officially specifies 1,600 t of Ship propellant and 100+ t to orbit in the fully reusable configuration.
  • Reliability is becoming architectural rather than aspirational. Flight 13 demonstrated full-duration ascent, payload deployment, an in-space Raptor restart and an intact Ship splashdown. That’s most of the ingredients needed before responsibly committing a Ship to orbit.
  • Flight 14 deliberately gives up reuse. Both stages are being expended/splashed down. So reaching orbit today does not simultaneously demonstrate the architecture on which Starship’s economics depend.
  • The really important remaining problem has shifted from rocket equation to operations: reliable Ship reentry → tower catch → booster and Ship turnaround → repeated flight of the same hardware → high launch cadence → orbital propellant transfer.

On the “$10/kg” vision, there’s been a fairly substantial retreat in the near-term target. SpaceX’s current investor disclosure says V3 should deliver about 100 t, V4 potentially 200 t, and Starship may ultimately reduce historical launch costs by “99% or more.” Against the NASA historical figure SpaceX cites of $18,500/kg, that’s implicitly <$185/kg, not $10/kg.

That’s an important distinction from Musk’s most aggressive early Starship rhetoric. $10/kg requires Starship to behave much more like an airliner than a reusable Falcon 9: extremely high hardware utilization, very little refurbishment, cheap ground operations, lots of flights per vehicle, and consistently full payloads. V3 doesn’t really abandon that theoretical endpoint, but it no longer looks like the natural economics of merely making Starship work.

I’d summarize the evolution as:

Original Starship dream: ~100–150 t + complete reuse + near-immediate turnaround + enormous cadence ⇒ eventually ~$10/kg.

V3 engineering reality: ~100 t reusable payload + much more sophisticated vehicle + heat shield/reentry/catch/refurbishment still being solved ⇒ SpaceX is presently talking in terms consistent with roughly $100–200/kg as the nearer economic ambition, while retaining much lower costs as a possible long-run endpoint.

And there’s a subtle irony here: V3 is simultaneously simpler and more complicated than the original Starship concept. Raptor 3 and structural integration simplify the vehicle, but experience has revealed that rapid full reuse is a much harder system problem—thermal protection, engine relight, propellant management, catches, pad infrastructure, inspection, refurbishment, regulatory cadence. The original “$10/kg” intuition arguably underestimated all the non-rocket parts of making a rocket behave like transportation.

from Protocol Institute Blyg ↗ · snapshot of v1

read the thread →

Created: Sep 28, 2026

In response to Venkatesh Rao's Blyg ↗

thread · 1 quoted

The story it turns out is even weirder than I thought.

A few pieces of it:

  1. Apples didn't start small and sour. In the wild Tian Shan forests of Kazakhstan, Malus sieversii already produced big, sweet, wildly flavorful fruit — hazelnut, anise, honey, berry notes — and a small fraction of wild trees are essentially supermarket quality, which almost never happens with wild fruit. The reason seems to be the bears: they prefer the same large, sweet, red apples we do, and they're the ones dispersing the seeds. So the forest had been running human-style selection for us, without us. (BBC Future, "Kazakhstan's treasure trove of wildly-flavoured apples")

  2. Moving west made them more diverse, not less. Carried along the horse/silk routes, those Tien Shan apples crossed with the Caucasian M. orientalis and then heavily with the European crabapple M. sylvestris. Modern dessert apples are roughly a third sieversii and a third sylvestris by ancestry. Domestication here wasn't a bottleneck — it was hybridization. The cultivated apple's pan-genome is larger than either wild parent's.

  3. Then America did the Tien Shan experiment again, for booze. Cider was the default drink of early colonists, and cider doesn't need a good variety — so people planted seeds rather than grafting. Every apple seed is genetically novel, so this was an enormous continental breeding trial. Over 15,000 named American cultivars emerged by the mid-19th century; the USDA has documented about 16,350, most now extinct or nearly so.

  4. China had its own apple, and lost it. Eastward, sieversii met the Siberian crabapple M. baccata and produced a parallel tradition — M. asiatica, M. prunifolia — cultivated for ~2,000 years. Then in the late 19th century the western hybrid lineage was reintroduced from Europe and America and commercially displaced it. Japan's industry is almost entirely a Western overlay.

![[73t9brh6db5ef66t10hx9h2qsj]]

  1. And the lost varieties are still out there, growing in people's yards. A gnarled old apple tree on Verona Island, Maine turned out, when Cameron Peace's lab at Washington State genotyped it, to exactly fill a "missing ancestor" slot they'd already inferred from the pedigrees of hundreds of American apples. It's Drap d'Or de Bretagne — Brittany's cloth of gold — a French cultivar so nearly extinct in Europe that the only other known copy was sitting in a University of Copenhagen collection. Settlers evidently carried it across the Atlantic and it quietly outlived its homeland. Two more genetically identical old trees turned up within about 20 miles, so someone had deliberately propagated it in that French-influenced stretch of Maine. Which makes the tree a kind of archaeological artifact made of living DNA: a lost progenitor still carrying ancestral variants that dropped out of the modern commercial breeding pool entirely. (Scientific American, "How Apple Detectives Solved the Mystery of an Ancient Tree—and Rewrote the History of Fruit" — in print, October 2026, as "The Mystery Tree")

There’s this theory that the maximal diversity of any evolutionary type is found at its origin point. Languages have most accents and dialects near origin, human genetic diversity is highest in east Africa apparently.

Though apples are native to Central Asia apparently, I’d guess more diversity wherever they were most aggressively bred, which might be Europe?

I was recently in London for work and went to the Marylebone farmers’ market mostly to sample apples. I was struck by how little overlap there was with the varieties I know from the US. Cox was the only one I recognized.

Why are the varieties so different? Is it mainly climate, or did apple growing simply diverge on either side of the Atlantic?

Short answer: Both, but the history matters more. Early American orchards were often grown from European apple seeds, and each seed produced a new variety. Growers kept and grafted the seedlings they liked, while British growers made their own selections. Climate shaped which apples did well, and local market stalls make that long divergence especially visible.

from blyg.bricolage.io ↗ · snapshot of v1

from Venkatesh Rao's Blyg ↗ · snapshot of v1

read the thread →

Created: Sep 27, 2026

I was recently in London for work and went to the Marylebone farmers’ market mostly to sample apples. I was struck by how little overlap there was with the varieties I know from the US. Cox was the only one I recognized.

Why are the varieties so different? Is it mainly climate, or did apple growing simply diverge on either side of the Atlantic?

Short answer: Both, but the history matters more. Early American orchards were often grown from European apple seeds, and each seed produced a new variety. Growers kept and grafted the seedlings they liked, while British growers made their own selections. Climate shaped which apples did well, and local market stalls make that long divergence especially visible.

Created: Sep 27, 2026

In response to Aneesh's Blyg ↗

thread · 1 quoted

There definitely feels like there's a there there with Blygger. Though distributed anything is rough for normies — needs a Bluesky-style frontend for that perhaps.

But it hits this nicely:

"Something old, something new, something borrowed, something blue."

protocol adopter go brrr

Early protocol adoption is the new early adoption.

from And Yet Here We Are 🚀 ↗ · snapshot of v1

from Summer Lightning ↗ · snapshot of v1

join us

from And Yet Here We Are 🚀 ↗ · snapshot of v1

read the thread →

v5

Created: Sep 27, 2026 Most recent: Sep 27, 2026, v5

I added an MCP server to Blygger Studio so a session can save drafts and publish fragments to my blyg. I do most of my thinking these days in Field Labs—sessions where I research, analyze, and synthesize—so I wanted a way to share interesting bits as they emerge.

This feels like it should be built into Blygger. I’d be happy to send a PR.

I do like the TK idea a lot though — I might need to steal that for my Field Lab or as a general MD editor feature. I actually generally just edit prose by prompting the AI to change things but TK does make for a nice balance between direct control and automation.

v3

Created: Sep 27, 2026 Most recent: Sep 27, 2026, v3

I was listening to Tragedy by Bee Gees which made my wife and idly wonder when they started using falsetto — turns out it was during the 1975 sessions for Main Course, when producer Arif Mardin asked if anyone could scream or shout some ad-libs over the tail end of "Nights on Broadway" — Barry tried, pushed up past the top of his range, and found this whole other voice sitting up there that nobody knew he had, so we of course needed to listen to that which surprised my wife as it turns out to be the song that's lightly re-written for this famous SNL skit "The Barry Gibb Talk Show"

Created: Sep 27, 2026

First blyg!

I've never used the TK notation before. Here's a quick history.

The mark is copy-desk shorthand for "to come," and like much of that trade's private orthography — hed, dek, graf, lede — it is deliberately misspelled so that it can never be mistaken for the thing itself. The digraph tk is close to orthographically impossible in English, which makes it trivially searchable: a page can be swept for unfinished business before it goes to press without a single false positive. Magazine shops, Time Inc.'s in particular, ran on it. Hed TK. Art TK. Fact-check TK. Doubled to TKTK when the hole was larger than a phrase, or stretched across a whole paragraph the writer knew had to exist but could not yet write. What survives in drafting software today is that habit, formalized: a placeholder that announces its own incompleteness, holds its place in the argument, and waits to be replaced by the sentence it was standing in for.

Created: Sep 27, 2026

Also reading

blogroll.opml — import this list into your feed reader